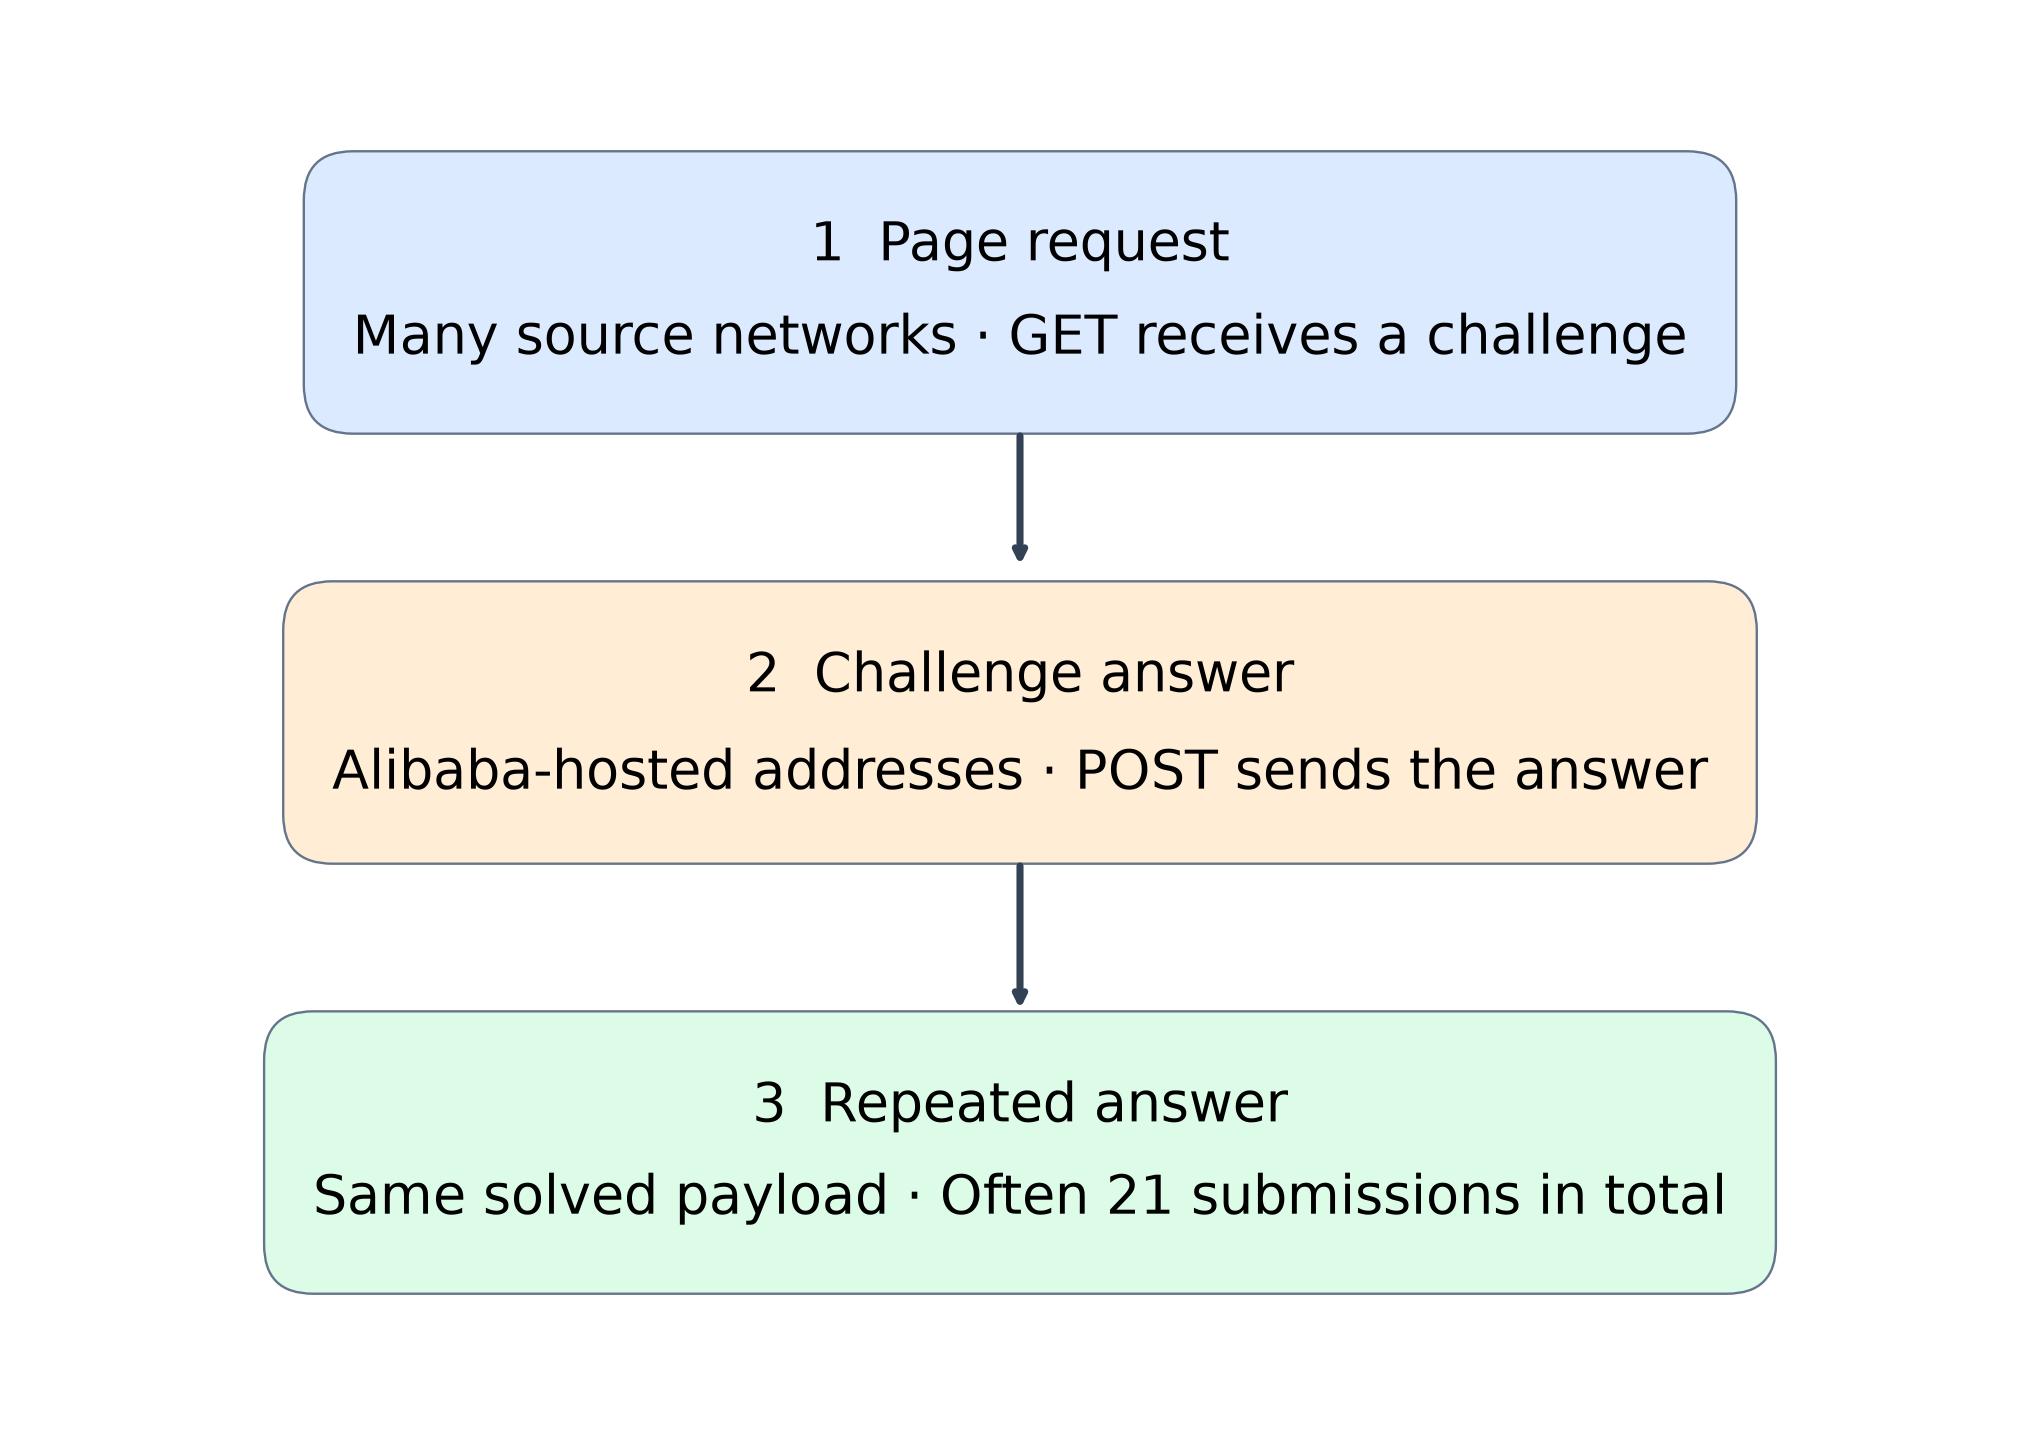
A page request arrived from one network. About a second and a half later, the same session sent its browser challenge answer from an Alibaba-hosted IP address. Then the answer came back again, often from another address. In most of the sessions we examined, there were 21 submissions in total.
We followed the requests to understand the network change, the repeated answers and what happened after the challenge was accepted.
The investigation covers saved traffic from 26 October 2026 at midnight to 27 October at 11:30 am AEDT. We also checked older records and found a fully traced example of the same behaviour on 15 April. The figures below describe those saved windows.
The request changed networks
We started with sessions that had a challenged page request followed by an Alibaba-attributed challenge submission on the same site. A session here is a grouping in the logs. It does not identify a person.
We found 113,253 paired sessions. In 111,035 of them, or 98.04%, both the IP address and the network changed between the page request and the first challenge submission. The median gap was 1.481 seconds.
The first requests came from 103,271 IP addresses across 182 countries. The challenge submissions were much more concentrated. Singapore was the recorded country for 98.55% of first submissions.
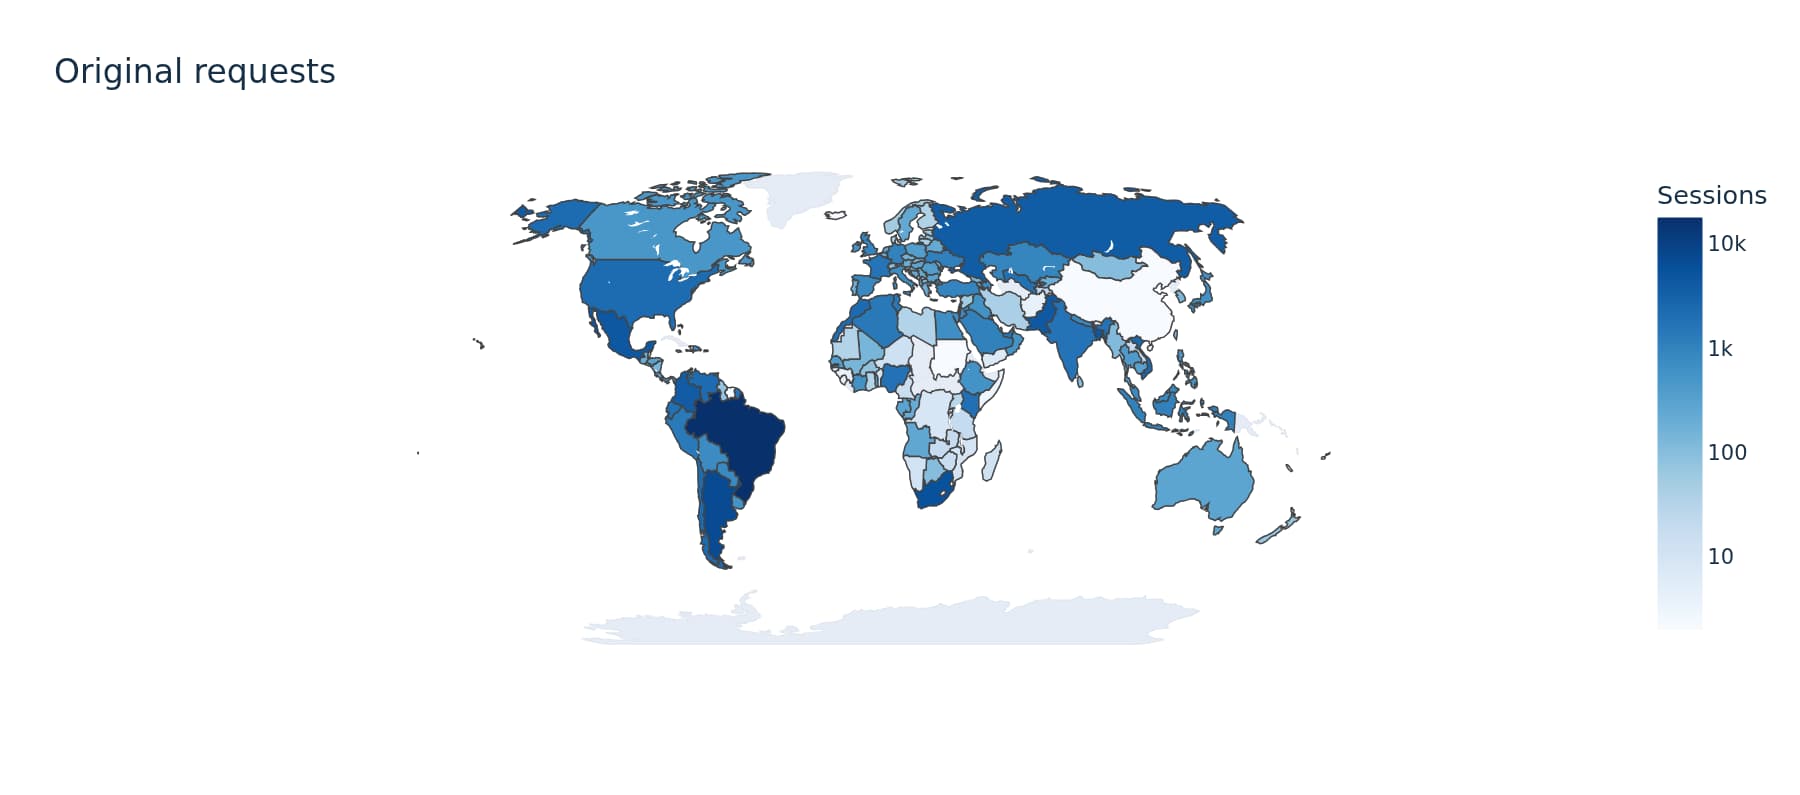
Original requests in the paired sessions. Country describes the observed IP address.
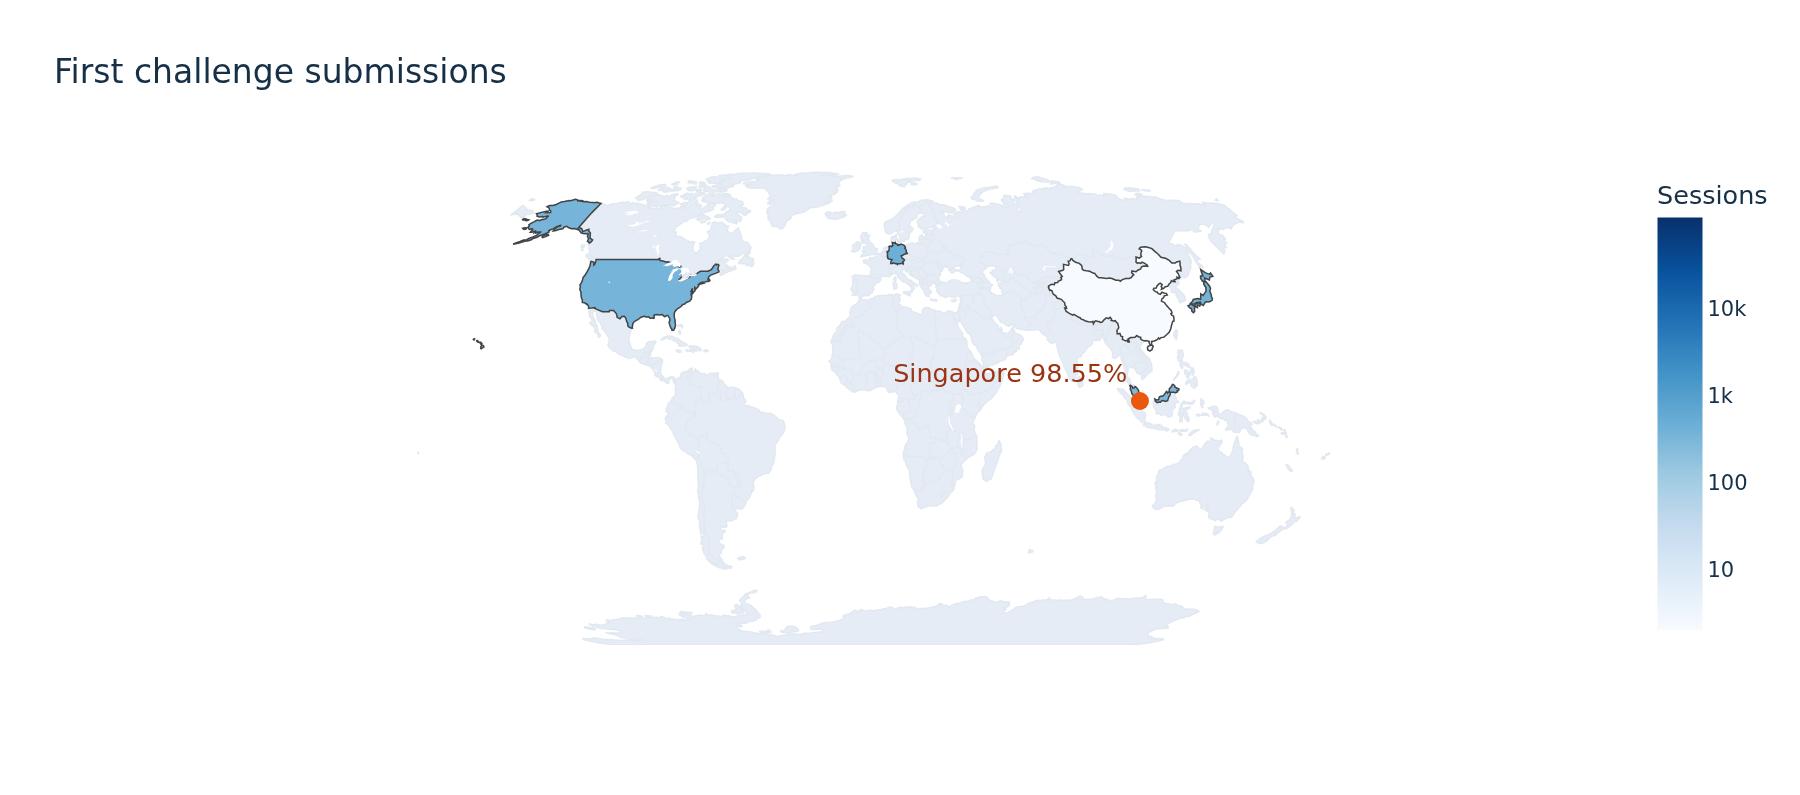
The first challenge answer in each paired session. IP geography cannot tell us where the browser code ran.
This resembles the split routing described in our residential proxy research. Different parts of a request sequence can leave through different networks. However, only 4,530 distinct original IPs in this sample carried an explicit residential proxy label. We cannot classify every original address as a residential proxy.
These pairs were selected because they included an Alibaba validation. Their 98.04% network-change rate describes that selected group, rather than all visitors to the sites.
Four address ranges carried most submissions
Four /24 ranges accounted for 99.90% of Alibaba validation requests in the main window. A /24 is a block of 256 IPv4 addresses.
| Observed range | Validation requests |
|---|---|
43.119.100.0/24 |
960,598 |
47.82.201.0/24 |
829,742 |
47.82.202.0/24 |
266,546 |
43.119.104.0/24 |
266,115 |
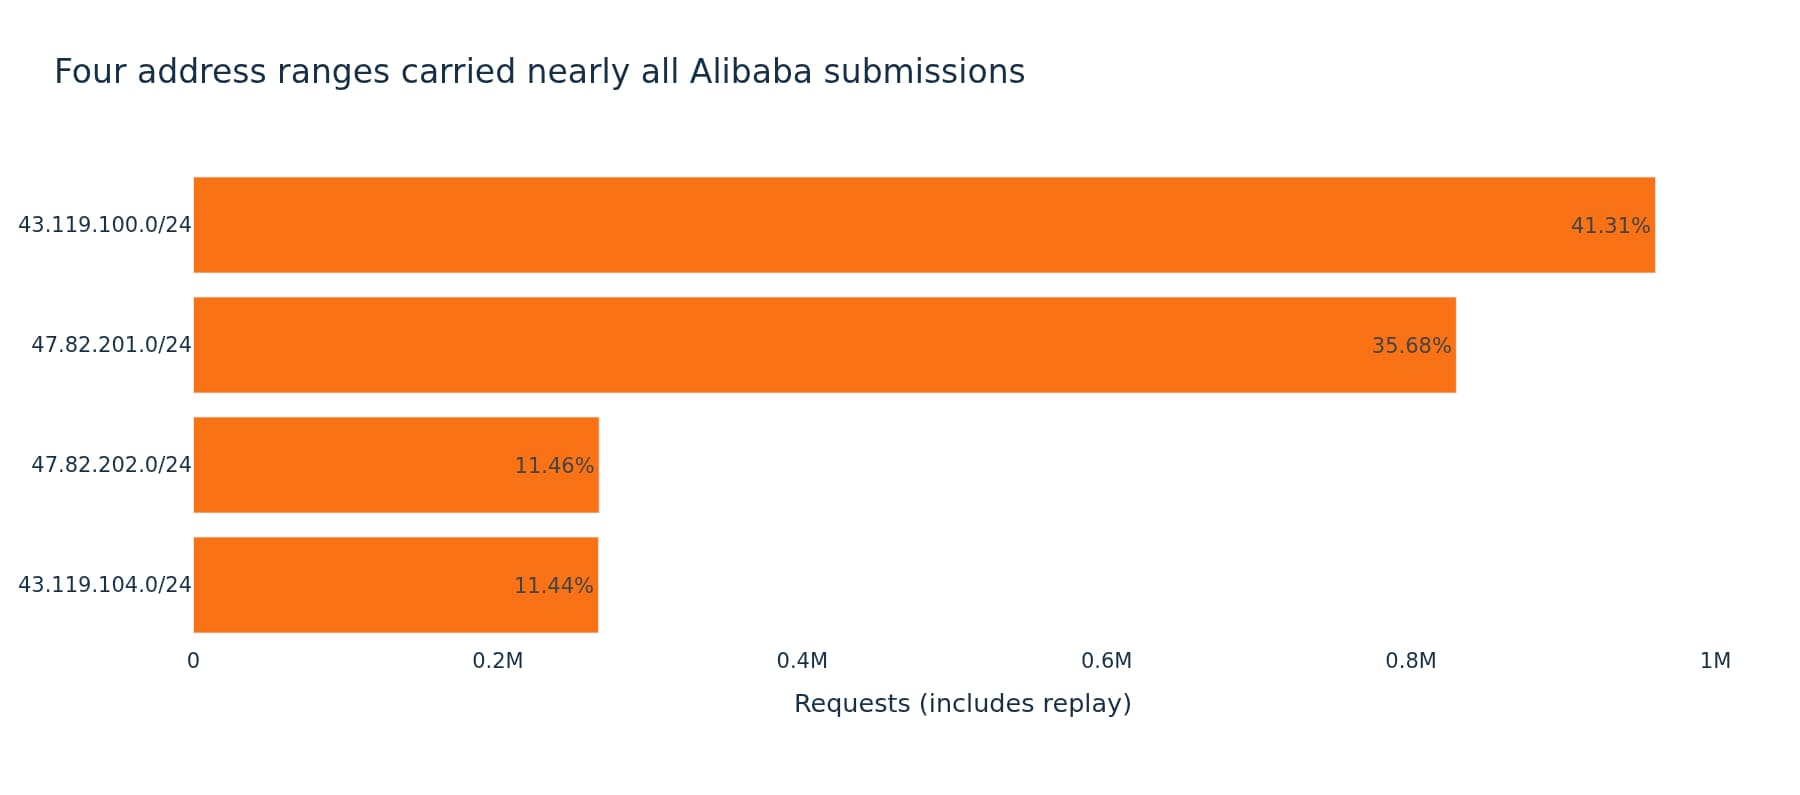
These counts include repeated submissions. An IP address in this table is a network exit, so the count of addresses cannot establish a count of machines or workers.
The flow chart shows how a wide spread of original countries connected to those submission pools and then to the protected sites. We have replaced customer names with consistent site numbers throughout the figures.
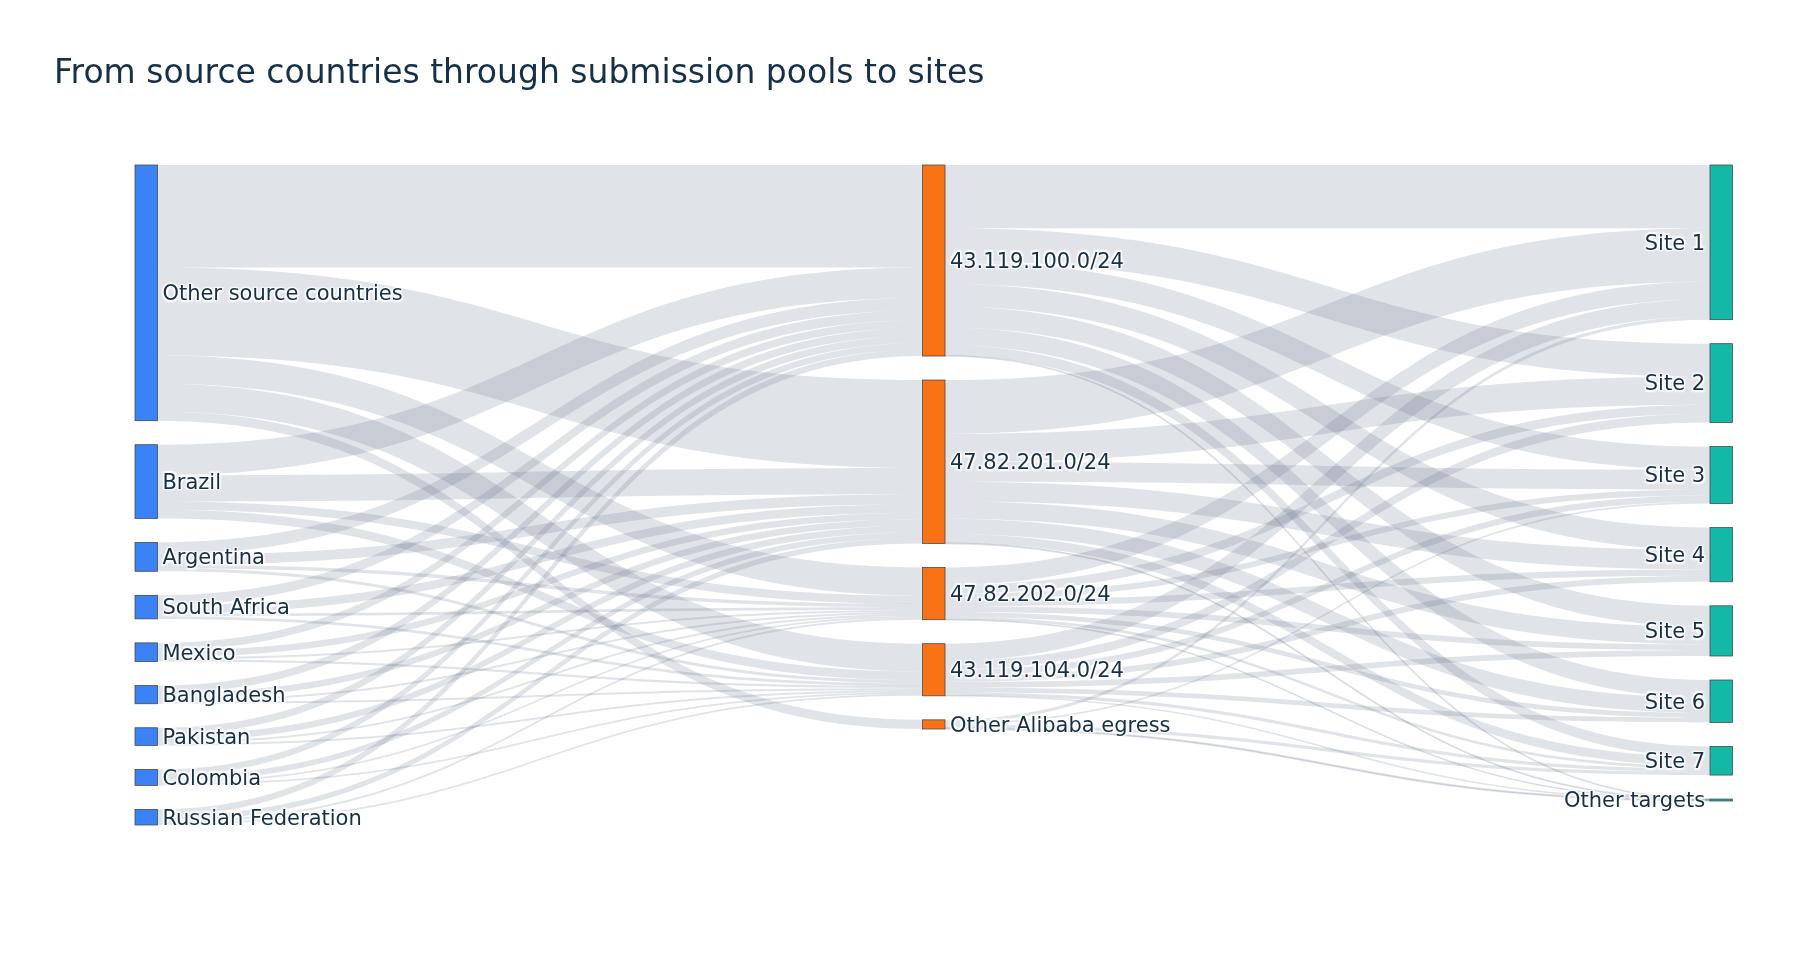
Each session contributes its original request and first submission. Later retries are excluded from this flow.
Alibaba is the hosting network recorded for the submission addresses. The records identify the hosting network; the customer operating the addresses remains unknown.
The browser claim stayed the same
Every paired session kept the same User-Agent string and requested path between its first page request and its first challenge submission. A User-Agent is the browser name a request reports about itself.
In 98,886 sessions, the TLS fingerprint changed. A TLS fingerprint summarises properties of the encrypted connection setup. Many clients can share one, but a change can help show that requests used different connection software.
The dominant pair was:
| Request stage | TLS JA4 fingerprint |
|---|---|
| Original page request | t13d1516h2_8daaf6152771_d8a2da3f94cd |
| Challenge submission | t13d521100_b262b3658495_8e6e362c5eac |
The same browser claim alongside a changed network and connection fingerprint fits a separate submission component. Two possible explanations are different proxy rules for different requests, or a service receiving a challenge and submitting the answer. The logs cannot distinguish them.
Our article on residential proxies and anti-detect browsers explains how network routing and browser presentation can change separately. This case gives us a request sequence to examine; it does not identify a particular browser product.
One answer kept coming back
107,454 paired sessions made exactly 21 validation submissions. We could match challenge-response records for 107,298 of those sessions. Every response-covered session reused one challenge solution and one browser identifier across its matched submissions.
In one fully traced example, 21 submissions arrived from 21 different Alibaba-hosted addresses. All used the same solution, browser identifier and browser-data payload.
Those repeats matter when reading the acceptance count. The response records attributed to Alibaba contained 2,305,119 accepted submissions and 49 rejected submissions. Repeated acceptance of one answer contributes many records, so that total cannot measure how many challenges were independently solved.
A later, narrower follow-up selected responses from the four submission pools and excluded every hostname containing edge. It counted 30,518 distinct challenge identifiers in the response records and 626,080 accepted response records. Solutions for 30,498 of those challenges appeared across multiple IPs. These follow-up counts use a different population from the main 113,253-session analysis.
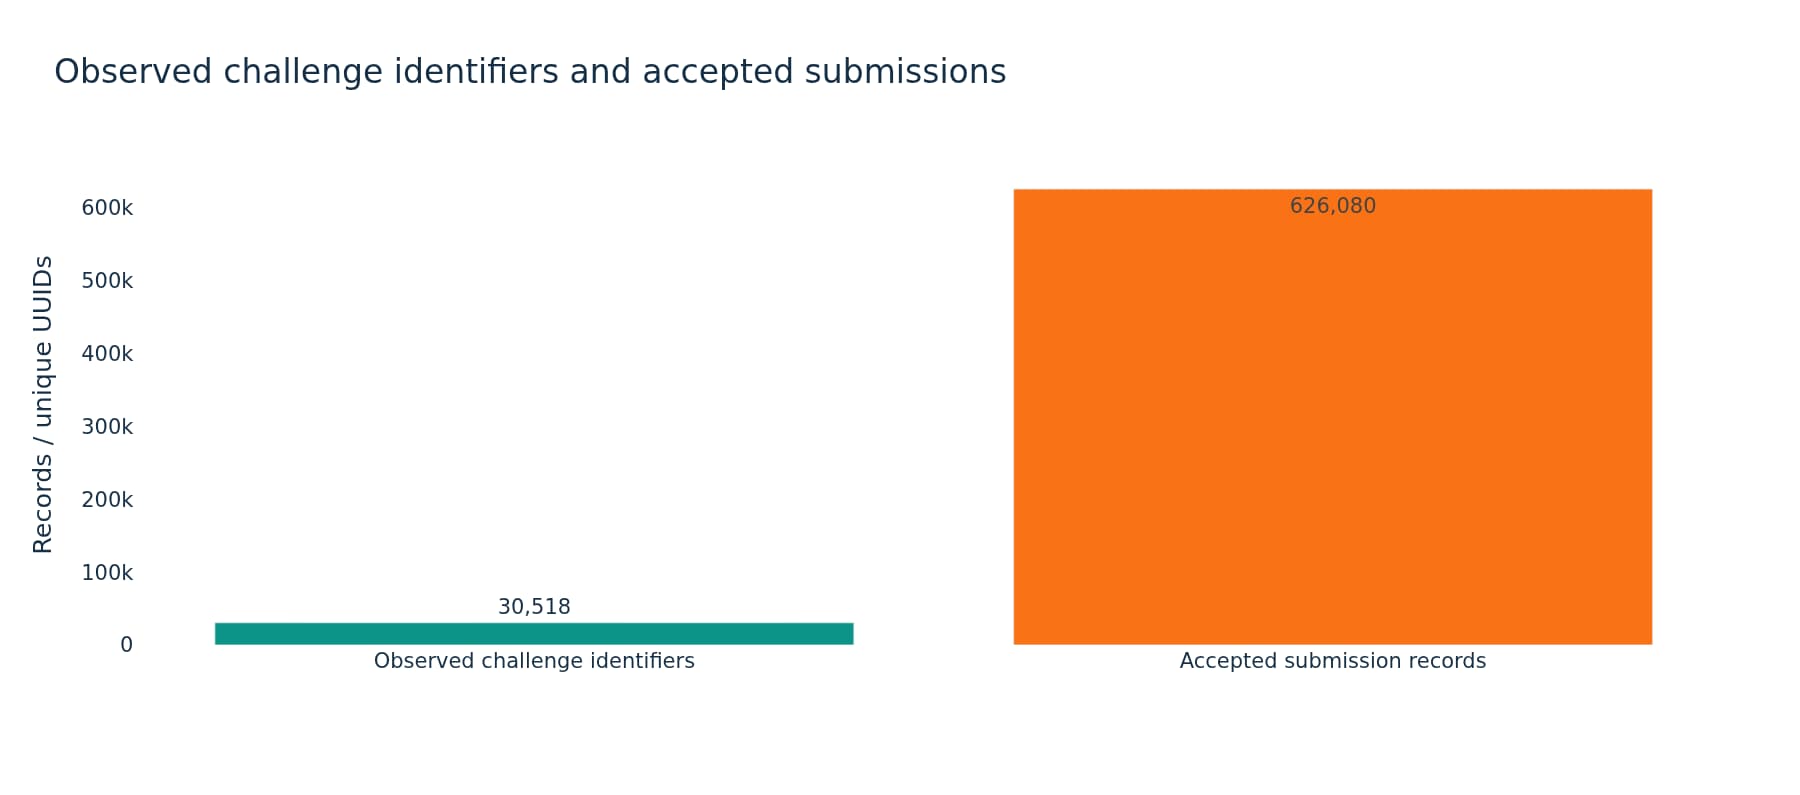
Count observed challenge identifiers and submissions separately. This is the four-pool, non-edge-host response sample; it is not a count of every challenge issued by the service. A large acceptance total can contain many copies of the same answer.
Redirects help explain the repeated count
The validation POSTs in the repeated sequence returned HTTP 307 redirects. A 307 preserves the request method, so a client following it can send another POST. The Fetch redirect algorithm stops after 20 followed redirects. An initial POST plus 20 followed redirects would produce 21 submissions.
That is a plausible explanation for the sequence. We did not establish the exact client implementation that sent every request. Our traced April example had 20 submissions, and other sessions had shorter bursts. A detector built around the number 21 alone would miss related behaviour.
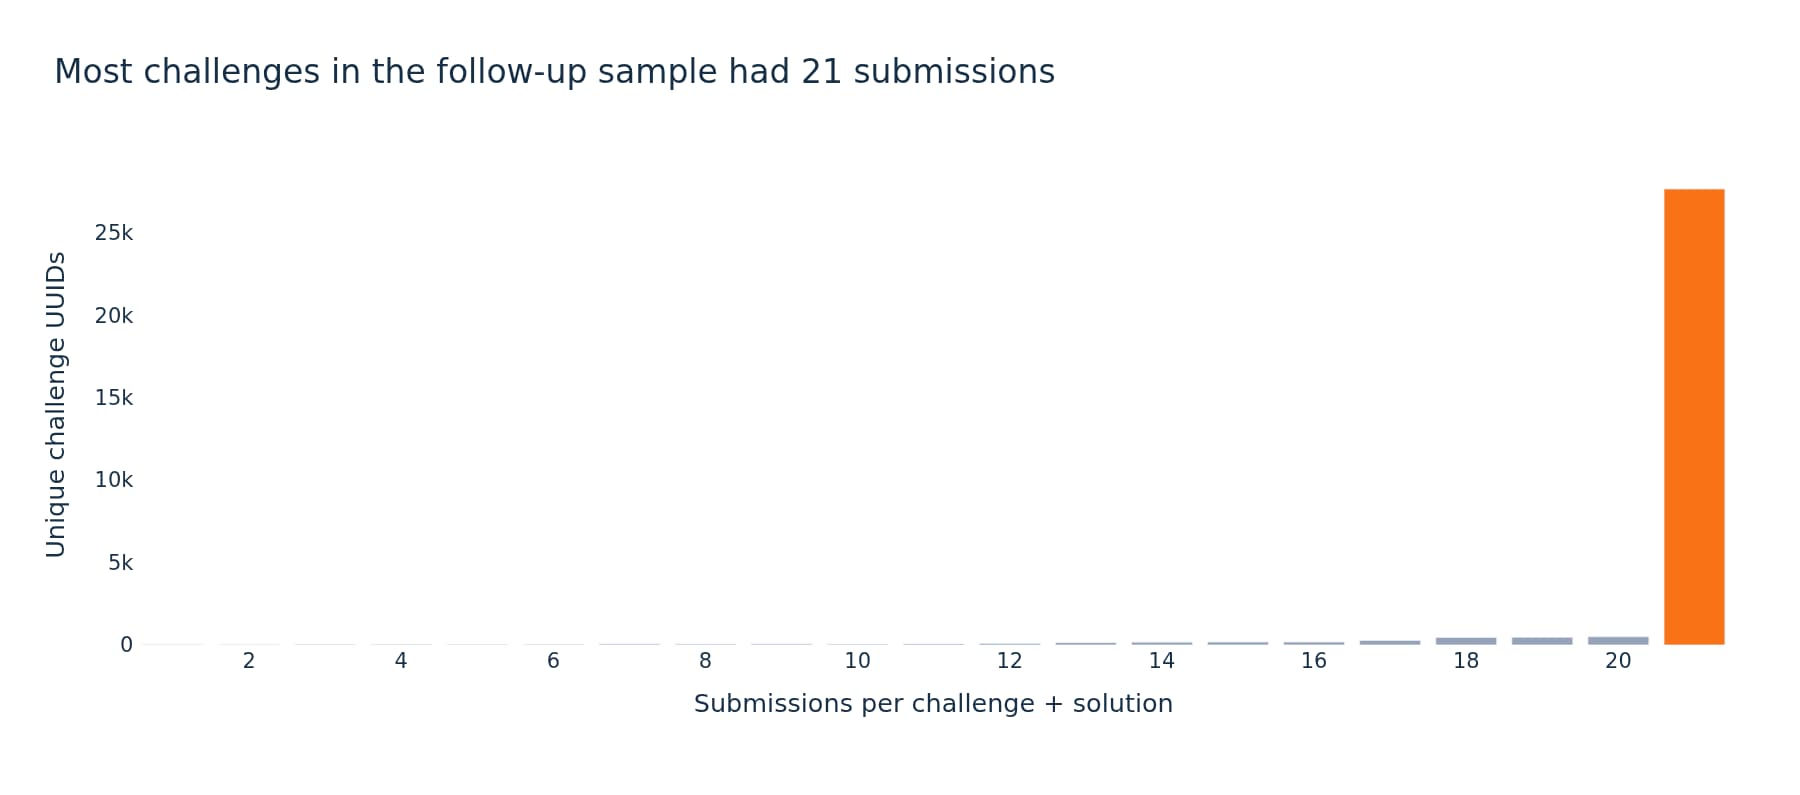
Twenty-one dominates this sample. Reuse of the same answer is the more useful behaviour to investigate.
The same answers linked the pools
Similar traffic volumes can make two networks look related. Shared solved payloads provide a more direct link.
In the narrower follow-up, 25,421 unique challenge solutions appeared in all four submission pools. The same solved answers were being submitted through different address ranges.
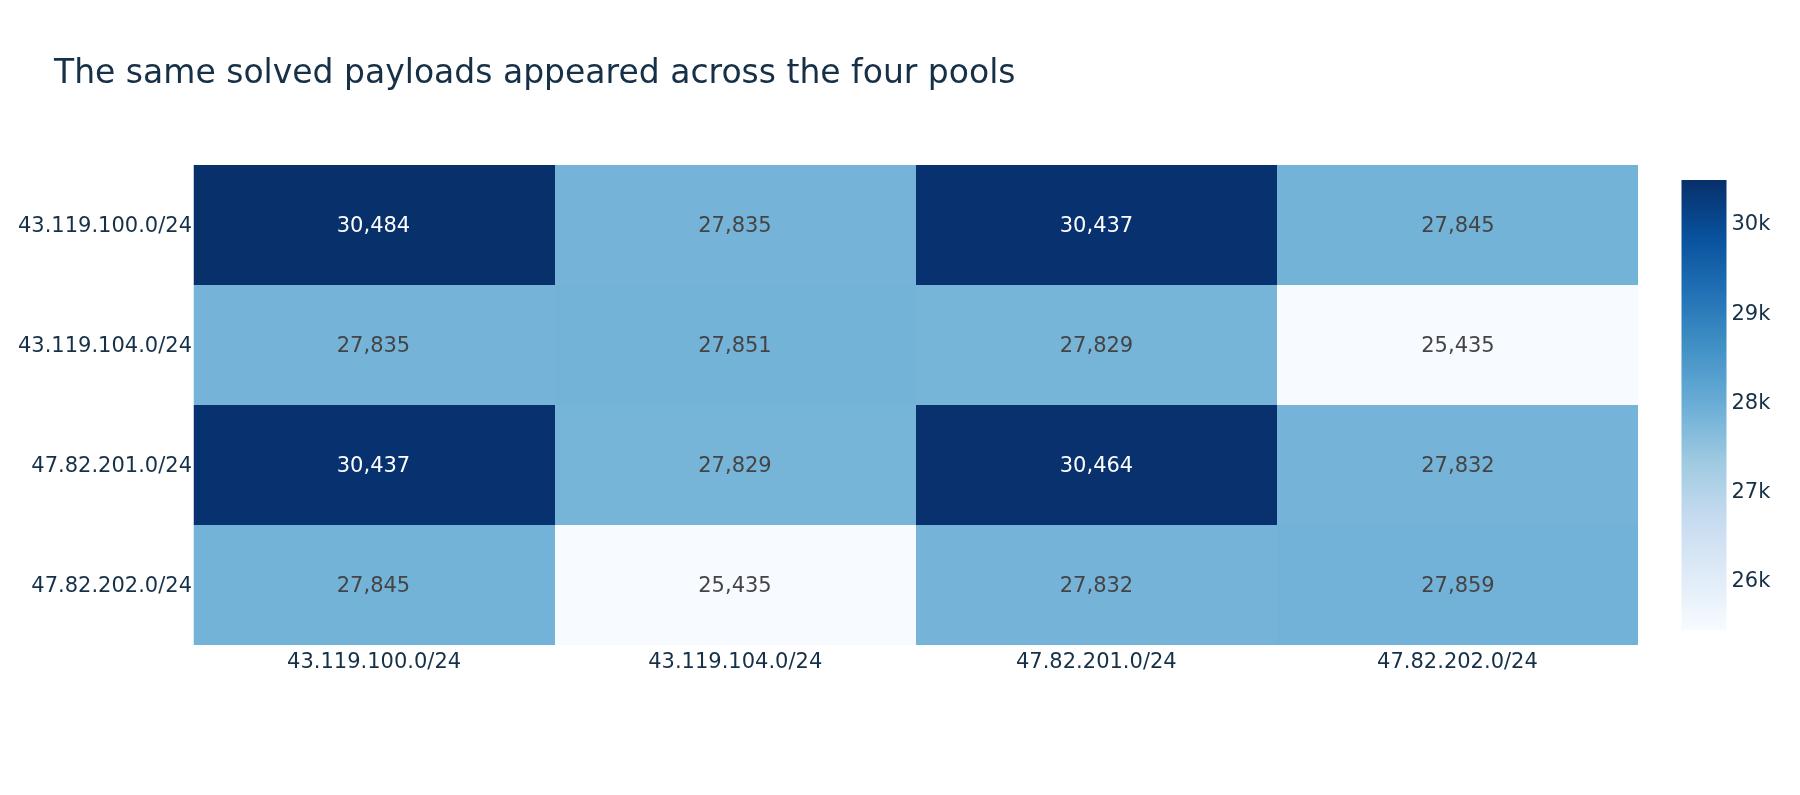
Shared solutions connect the submission traffic. The chart does not identify the operator or show how many computers were involved.
All four pools were active in every five-minute bucket of the 35.5-hour follow-up window. Their activity rose and fell together. Repeated submissions of shared answers help explain that timing similarity. The same retries contribute to both counts.
The pattern was already months old
We traced the same request flow to 15 April 2026. That session changed networks, used the dominant pair of TLS fingerprints and submitted one identical solved payload repeatedly. It made 20 accepted submissions through 18 Alibaba-hosted IPs.
Daily edge counts show how much larger the traffic became later in the year. Alibaba-attributed validation requests averaged 88,778 a day on 1–17 September and 1,862,584 a day on 18–26 October, about 21 times higher. The busiest full day was 20 October, with 2,653,940 requests.
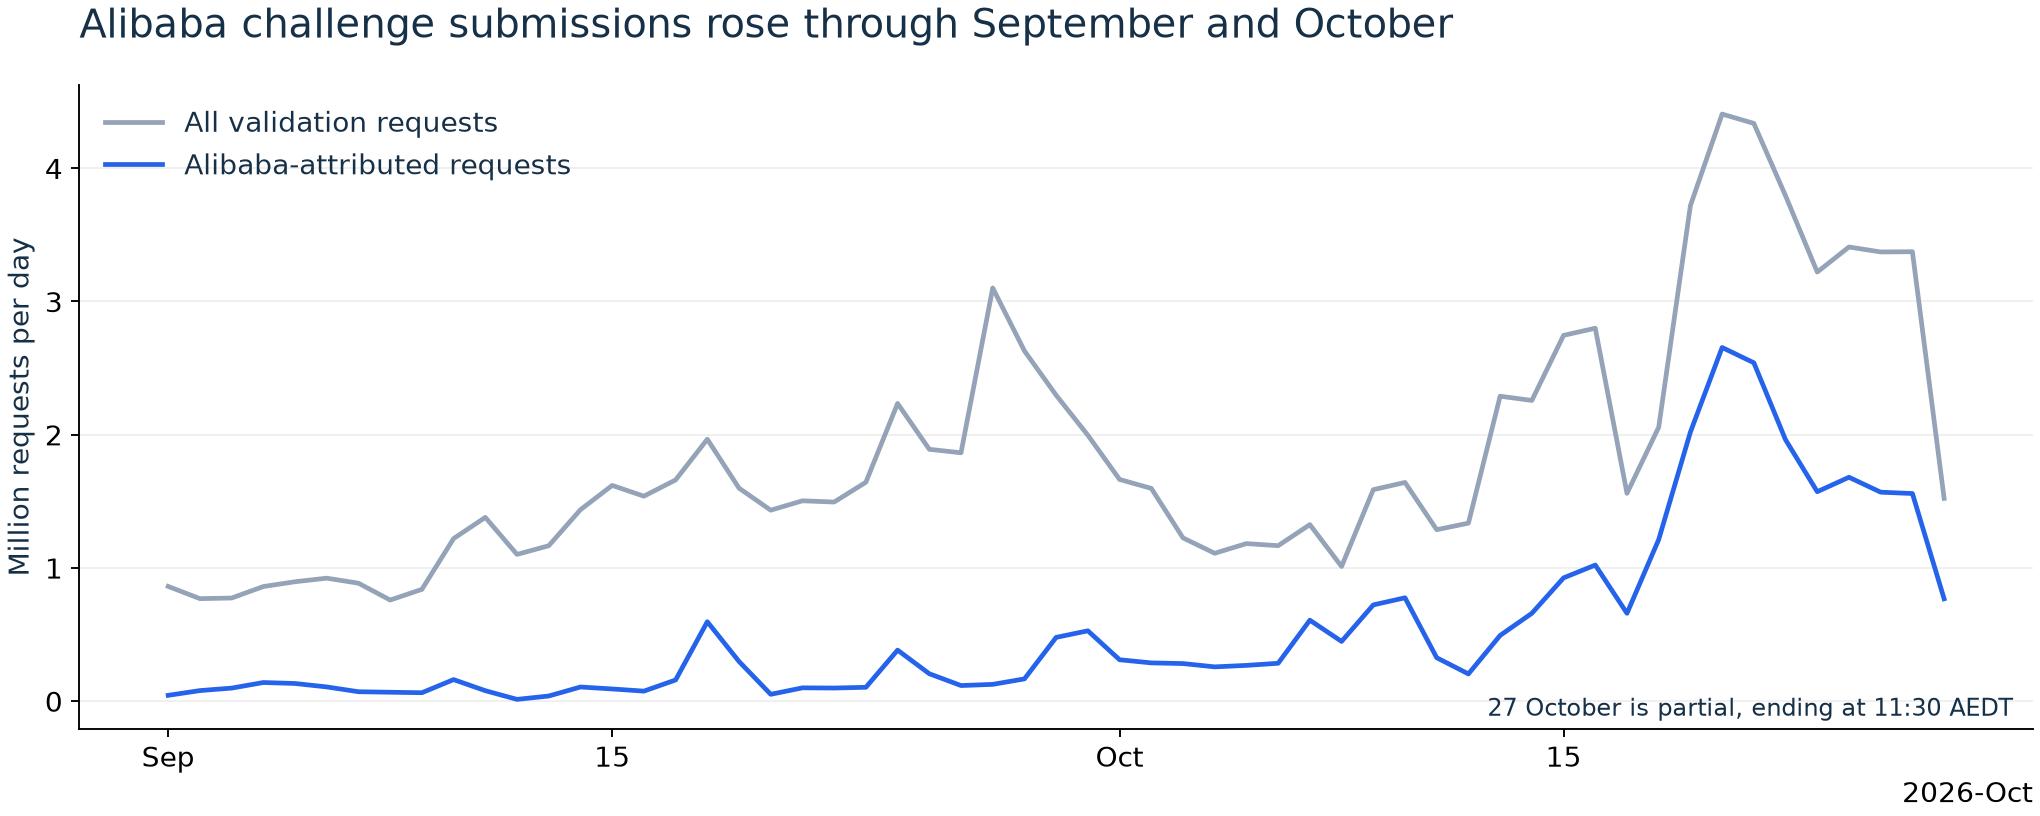
Counts include retries. The final day ends at 11:30 am AEDT and is incomplete. The increase does not establish one operator throughout the period.
We checked what happened after acceptance
Among the main paired sessions, 2,152 had a later ordinary GET in the same site and session. None of the 107,454 exactly-21 sessions had one during the observation window.
The narrower follow-up also found many challenged requests exploring combinations of search filters. Those requests covered 20,213 URLs with query parameters put in a consistent order. A separate search across the submission pools found ordinary GETs, but none matched or referred to an original challenged URL from this narrower sample within the available follow-up, capped at ten minutes. Of the 30,487 lifecycle sessions, 30,217 had at least ten minutes of observation after the first redirect.
This establishes repeated accepted challenge submissions and attempted browsing. Successful collection of the requested pages remains unverified. Requests using a new session or another route, or arriving after the cutoff, can escape this check.
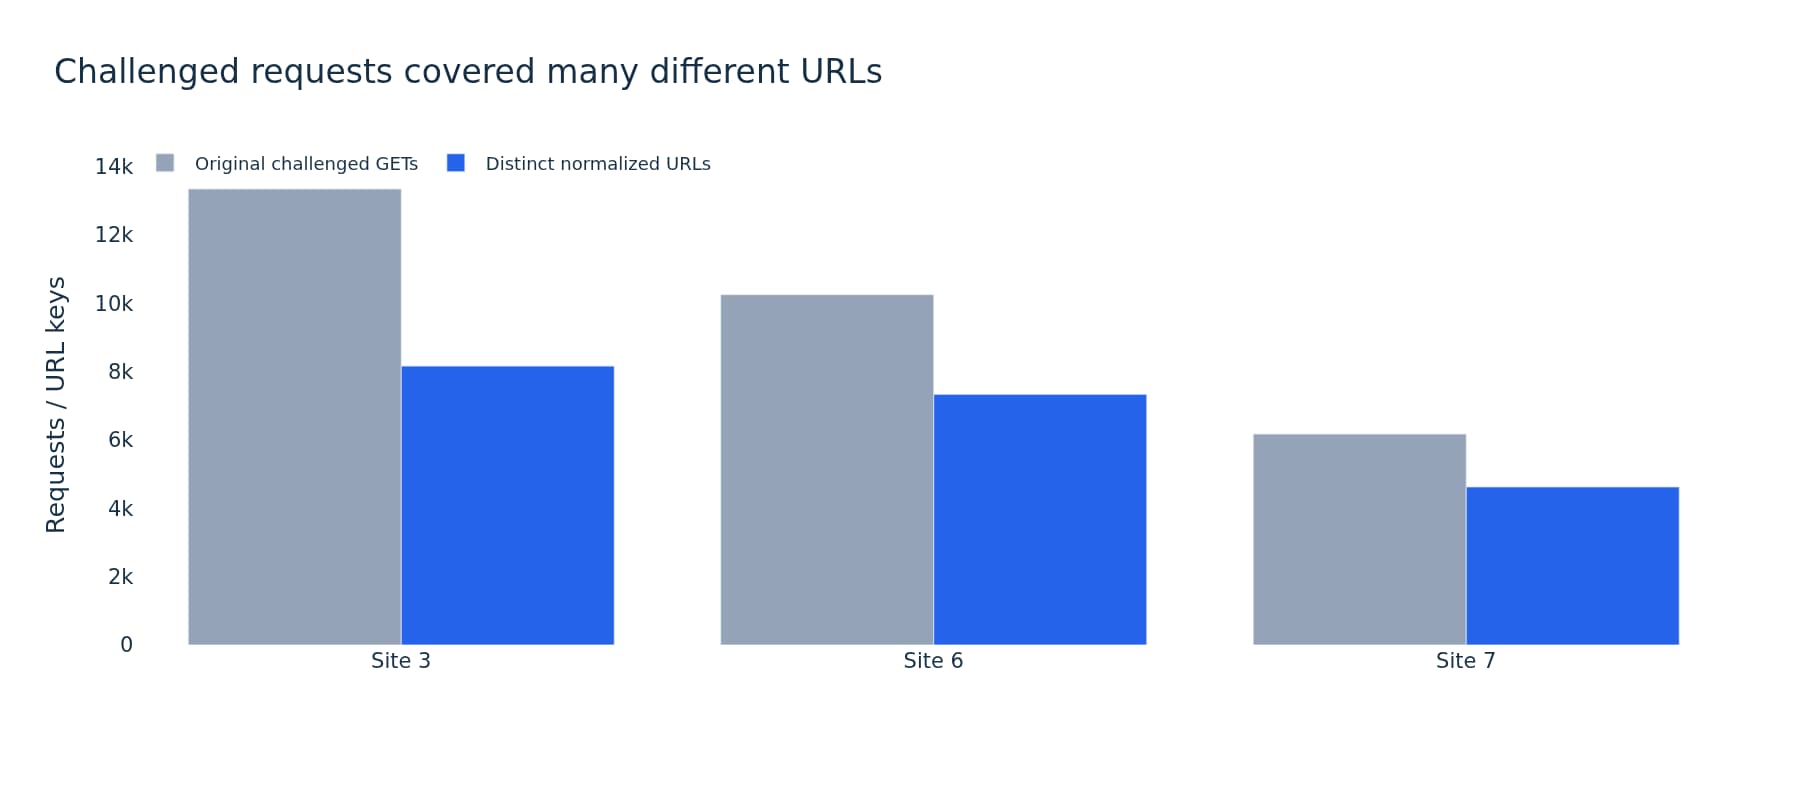
URL variety shows what the requests attempted. It does not show what content was collected.
Related research on automated scraping
Our AI and LLM web scraper guide explains how automated tools can use browsers and proxy networks to fetch pages. That background helps explain why a site should follow a request beyond its advertised browser name.
We did not identify an LLM provider, a training job or an AI agent in this traffic.
We also compared our findings with FlagThis's September crawler investigation. Its reported infrastructure and browser traits overlap with ours. We tested some of those leads against our own records. Our Lightpanda-labelled requests did not provide a matching site-and-URL sequence that would establish Lightpanda as the software submitting these answers.
The overlap provides research context. The software and operator remain unidentified.
What this changes for detection
A counter attached to one IP address loses much of the sequence when each request arrives through a different exit. This investigation shows why page requests, challenge submissions and later activity need to be reviewed together.
Useful checks include:
- Count unique issued challenges alongside submission volume.
- Look for reuse of the same answer across addresses and repeated redirects.
- Compare the network, connection fingerprint and browser claim at each stage.
- Keep the site, session and exact request link so retries cannot attach a decision to the wrong request.
- Check what happens after acceptance before reporting a bypass or successful scrape.
Any new control also needs testing against ordinary retries, mobile network changes and shared connections. We have not shown that blocking an entire hosting provider would be effective or proportionate.
We separately replayed graph-based anomaly configurations against saved traffic. They surfaced useful relationships, but extra findings also displaced existing ones in a limited review queue. Those tests remain a local evaluation. They do not establish a deployed detector for this full request sequence.
For more on the grouping tradeoff, see using network fingerprints in bot and rate-limit decisions.
More charts from the investigation
The static figures below preserve the remaining views from the saved reports, including the residential-proxy subsets and the comparison samples. Each uses its original population and window. They should be read separately rather than added together.
Original requests with a residential proxy label
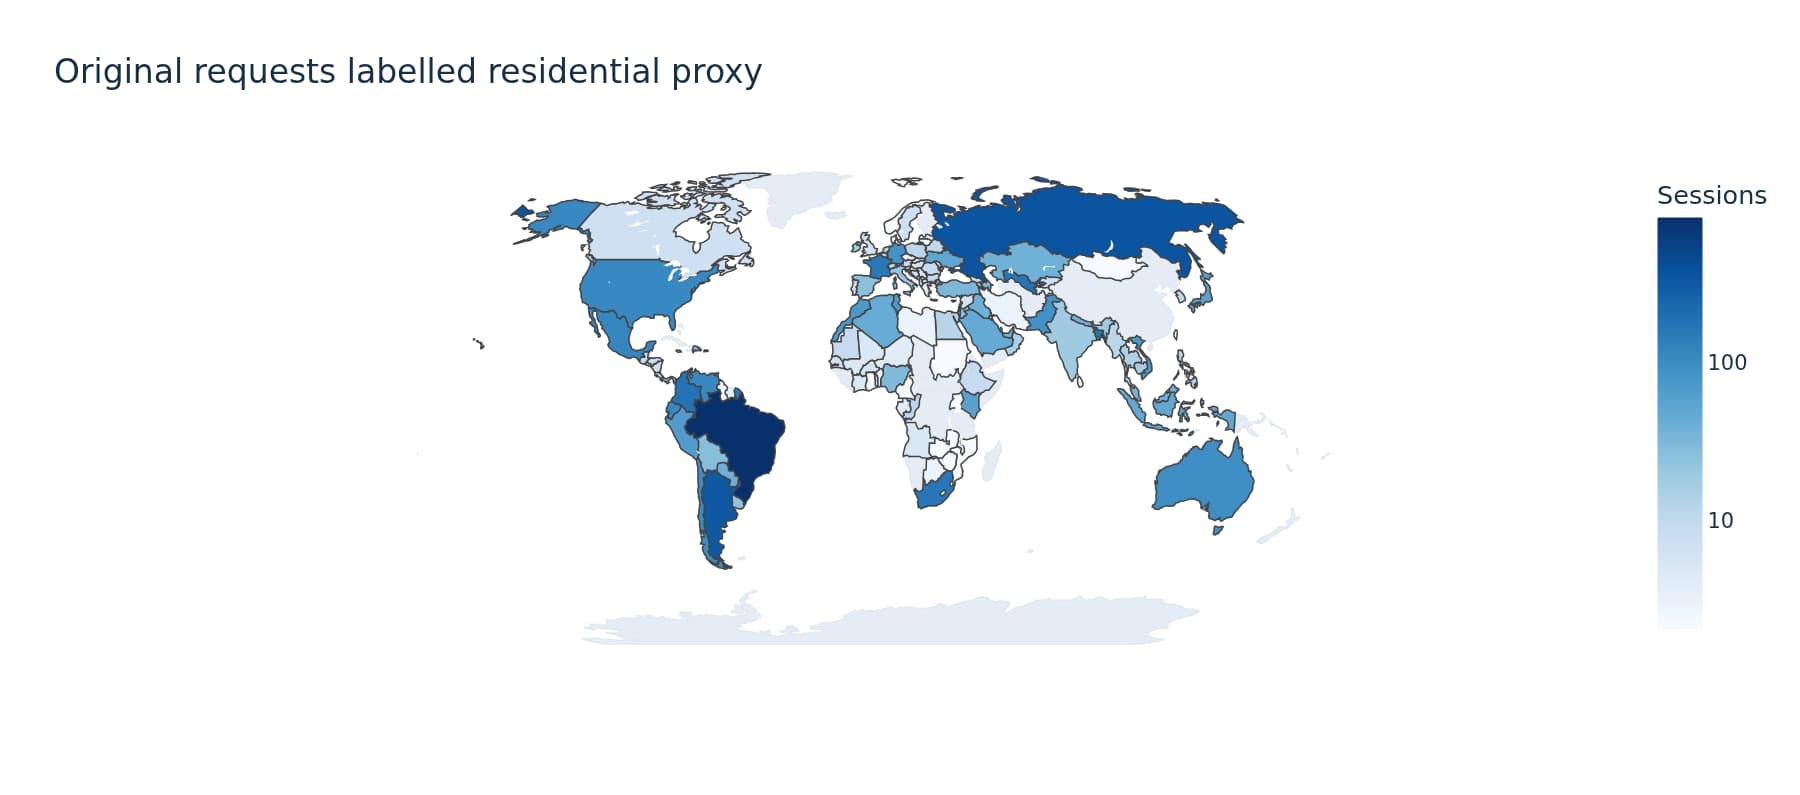
This subset uses explicit labels in the saved data. An unlabelled address is not automatically a direct connection.
Where the labelled subset sent its first answers
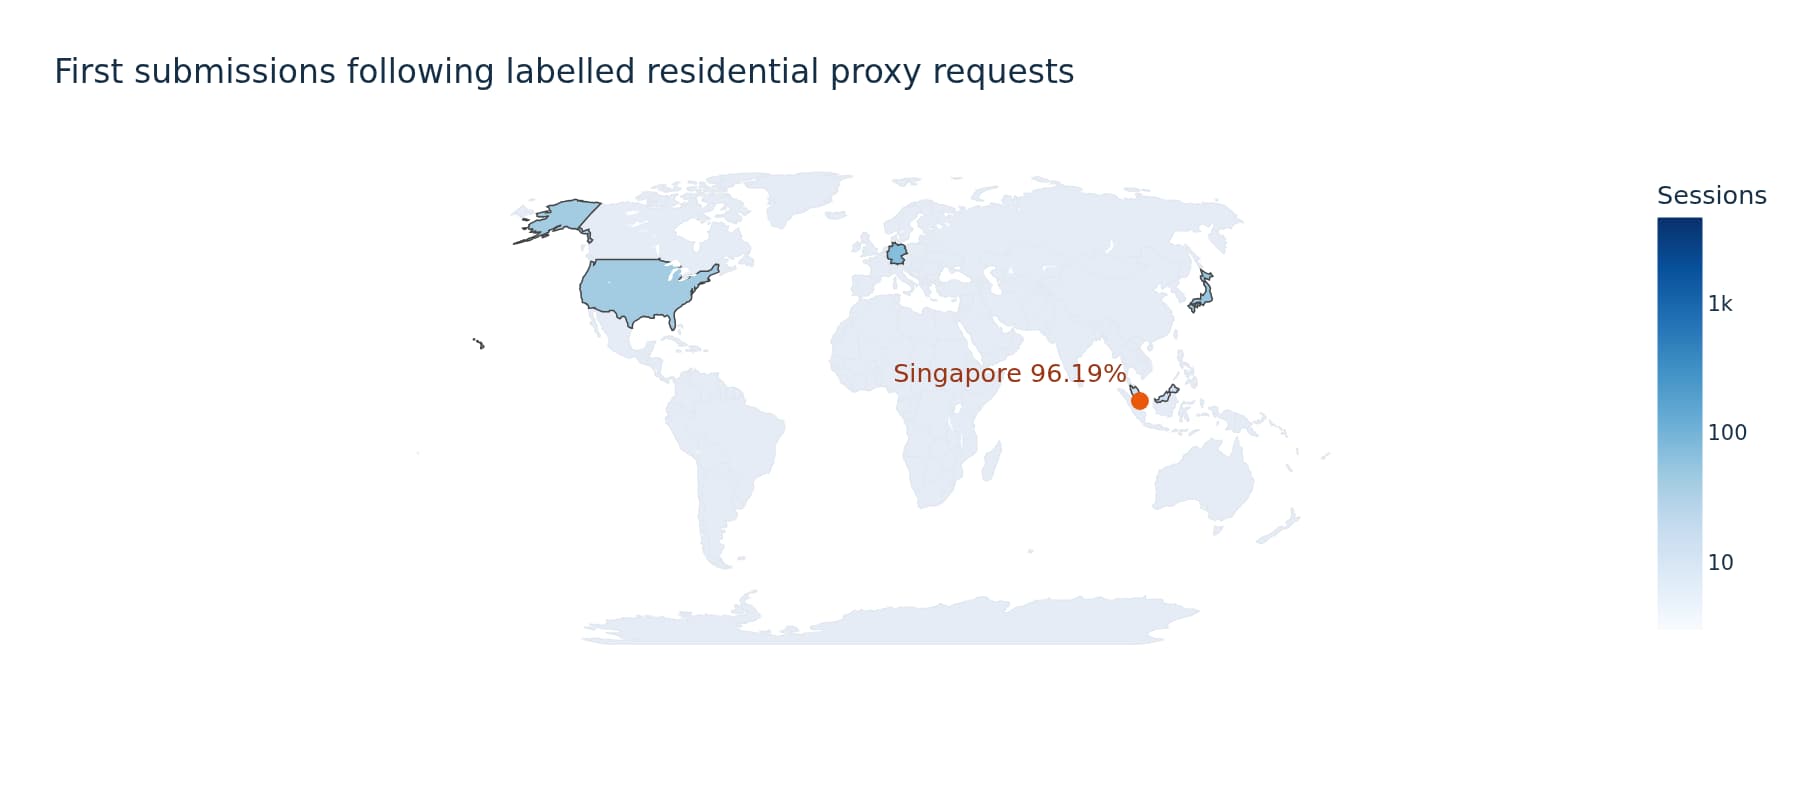
The country is the recorded location of the submission IP. This does not locate the browser.
The labelled residential proxy subset
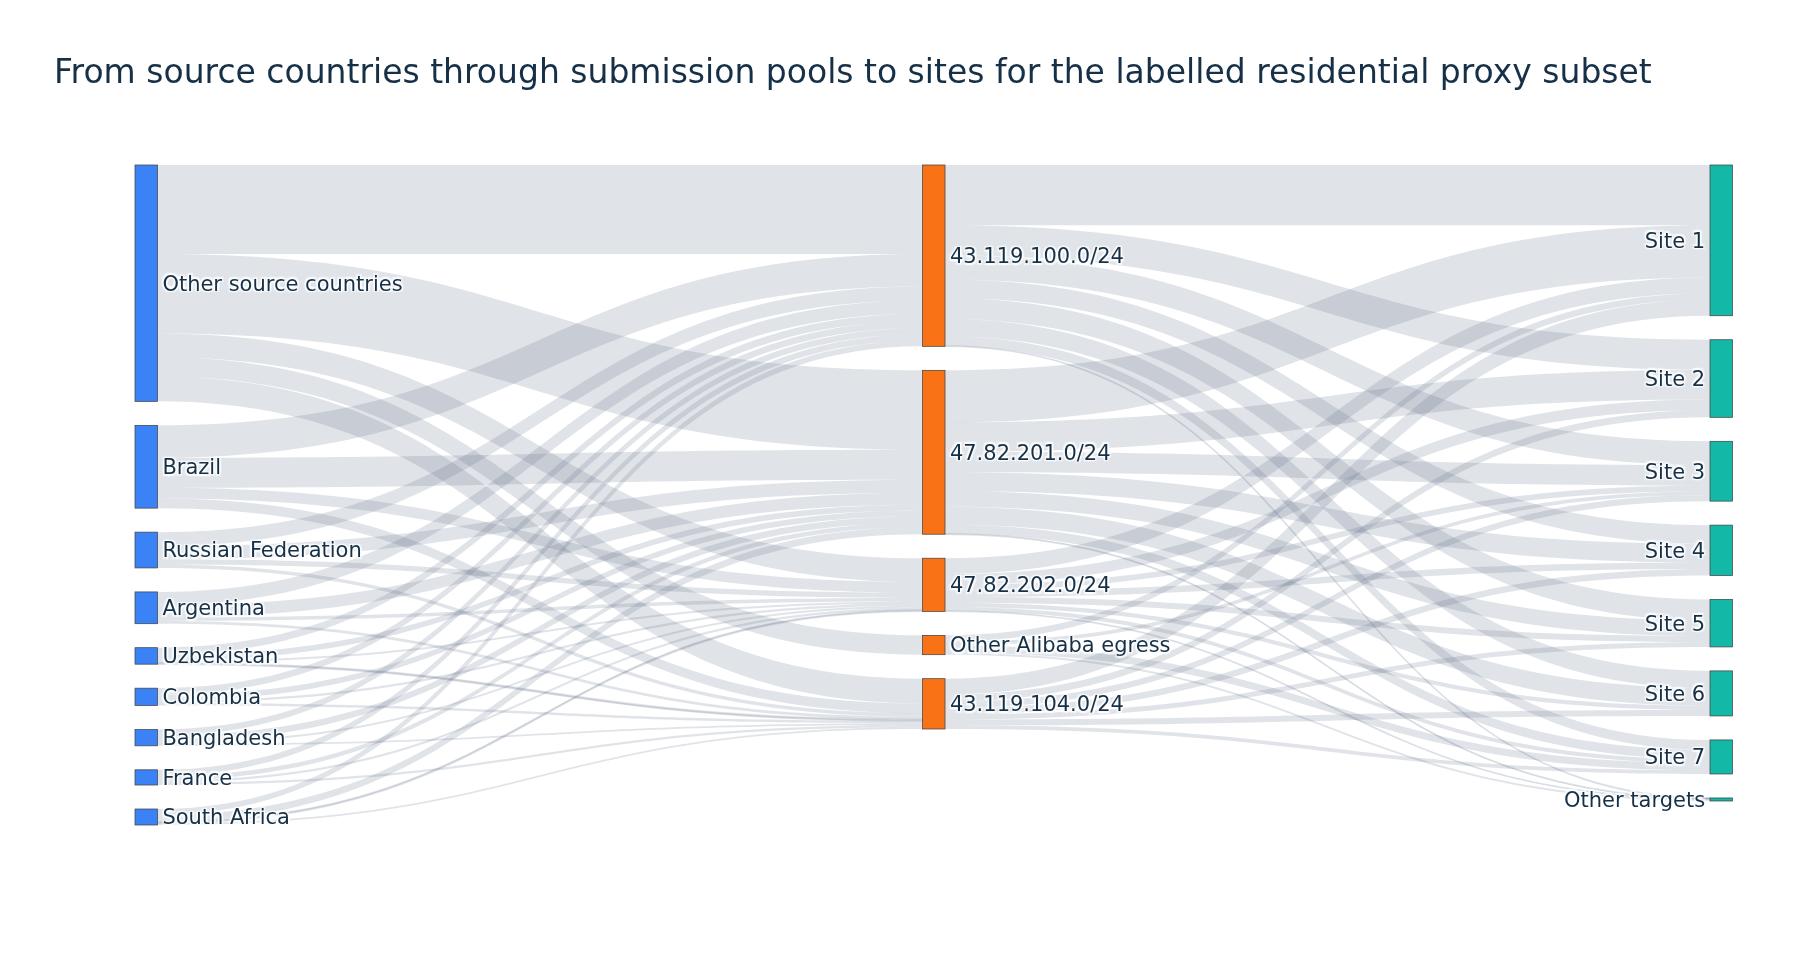
One original and first submission per paired session. Site aliases match the main flow chart.
Browser and header candidates across five samples
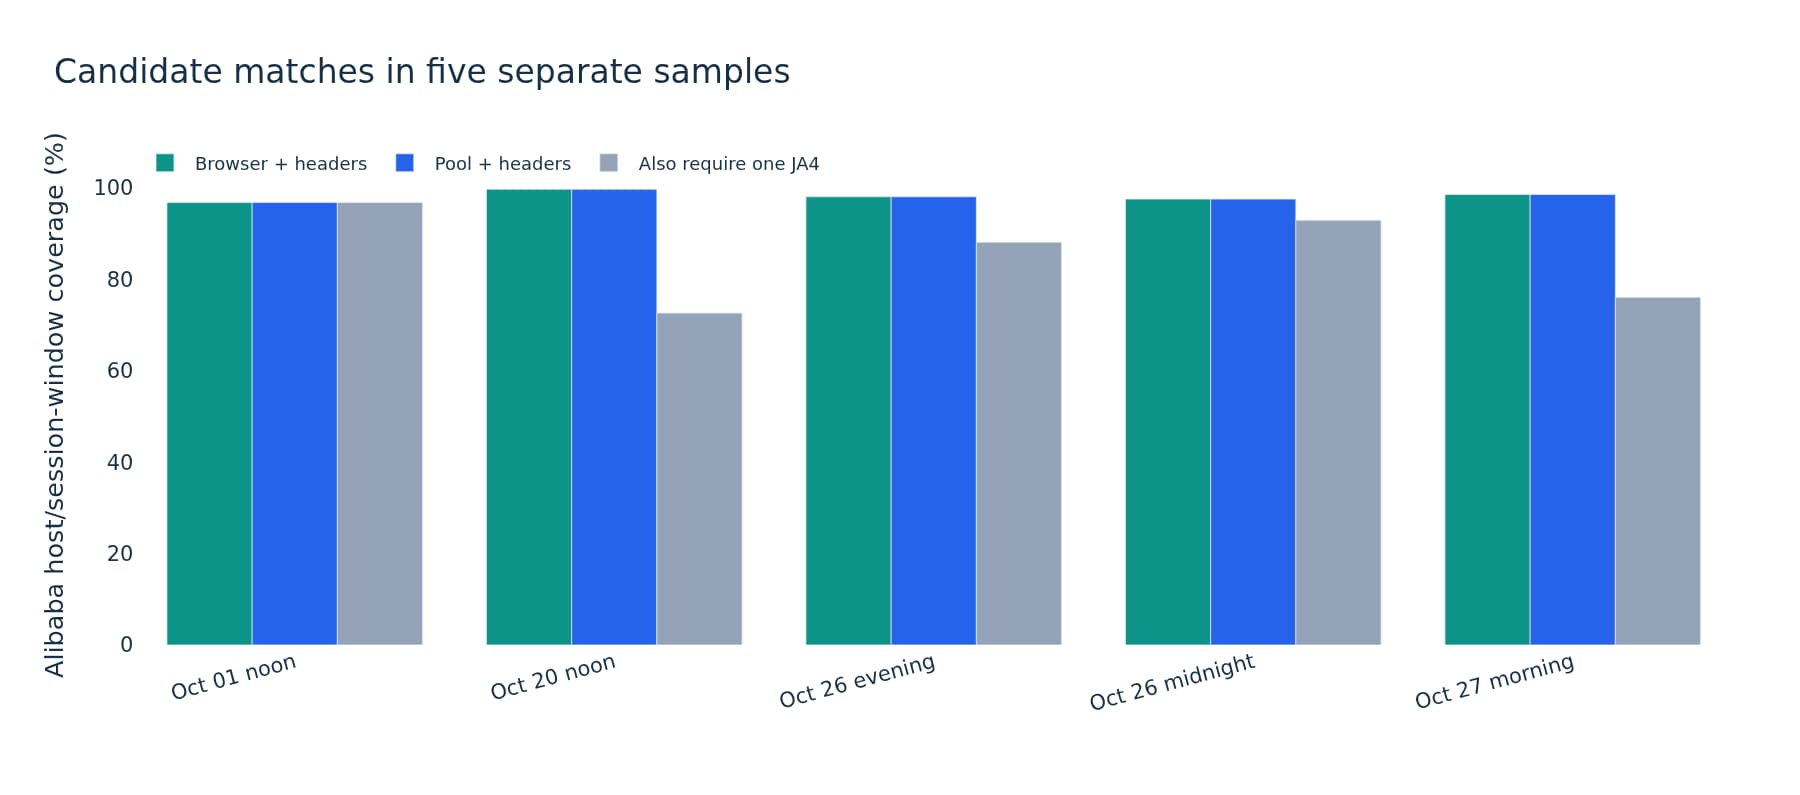
Five separate 30-minute samples. The compound browser/header candidate matched 7,991 of 8,104 Alibaba-attributed session-window observations and zero of 188,914 other-network observations. Network groups are not malicious and legitimate labels; these results do not establish a false-positive rate.
Individual signals also appear on other networks
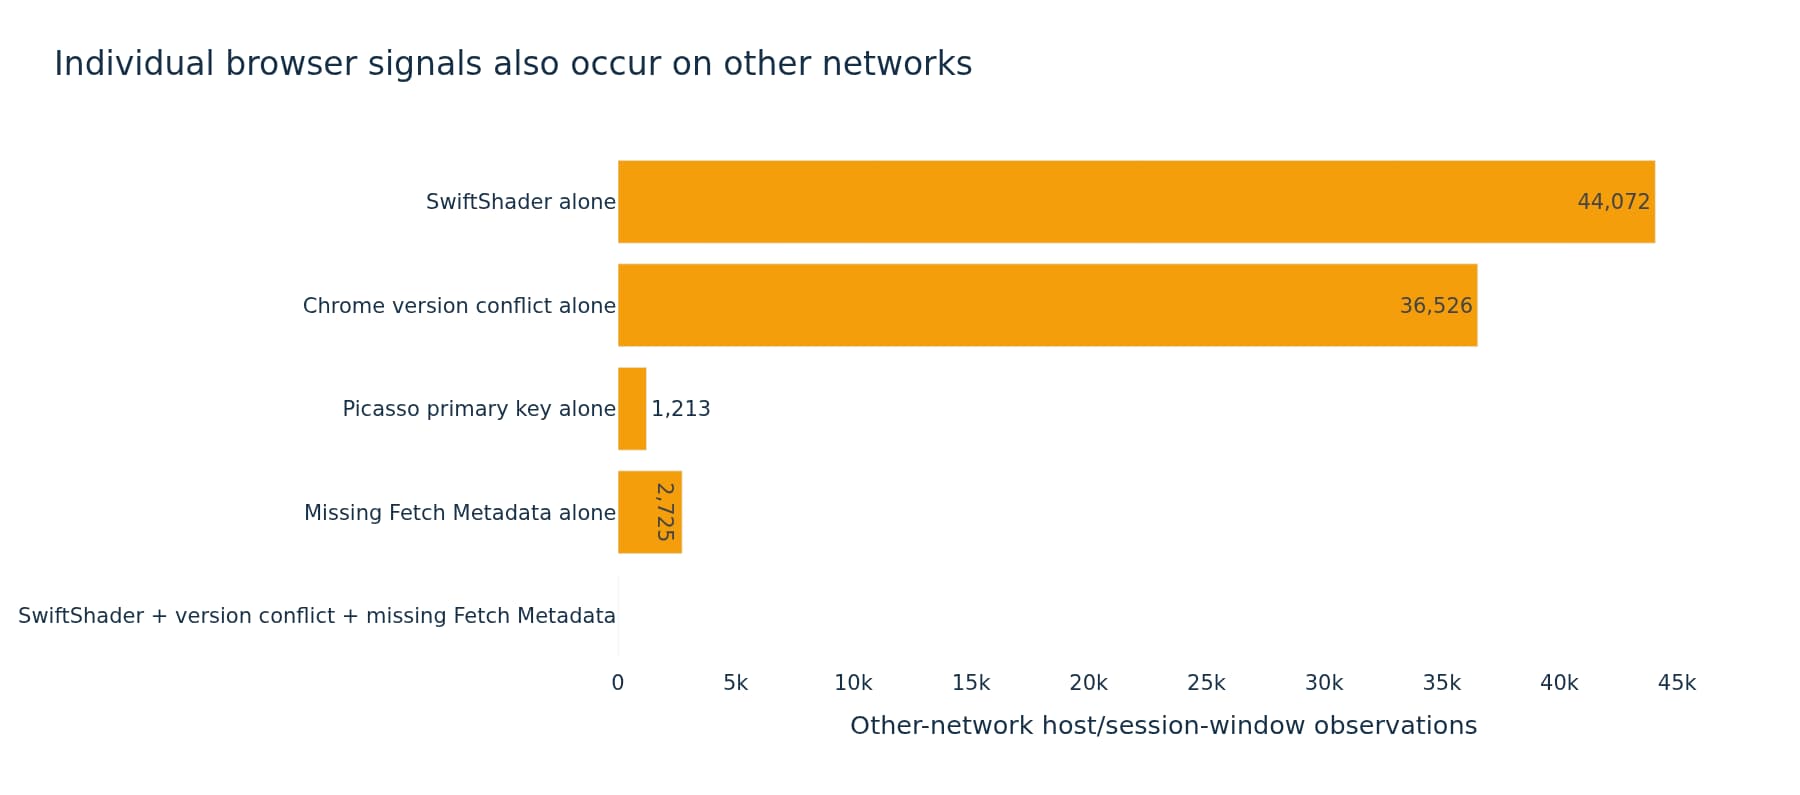
SwiftShader, version conflicts and missing browser headers each occur outside the selected network. The compound rule describes separation in these samples, rather than a proven block policy.
Connection timing within paired sessions
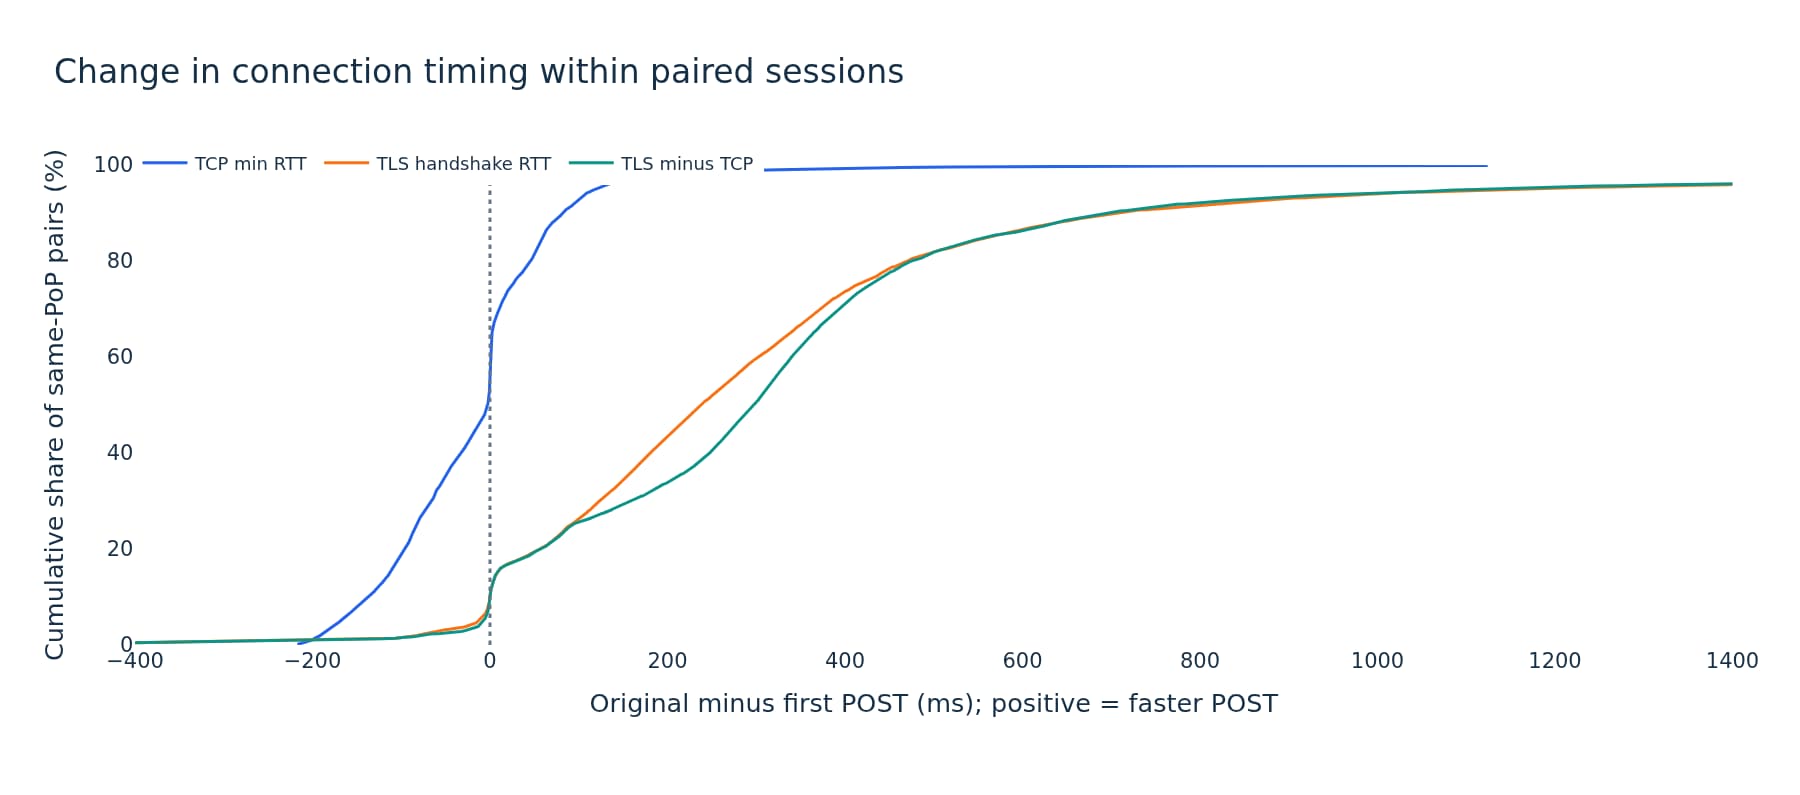
The plotted change is original minus first-submission timing. Among 6,355 same-service-location pairs, the median TLS reduction was about 236 ms. TCP changed little. Every hostname containing edge was excluded.
Timing in the labelled residential proxy subset
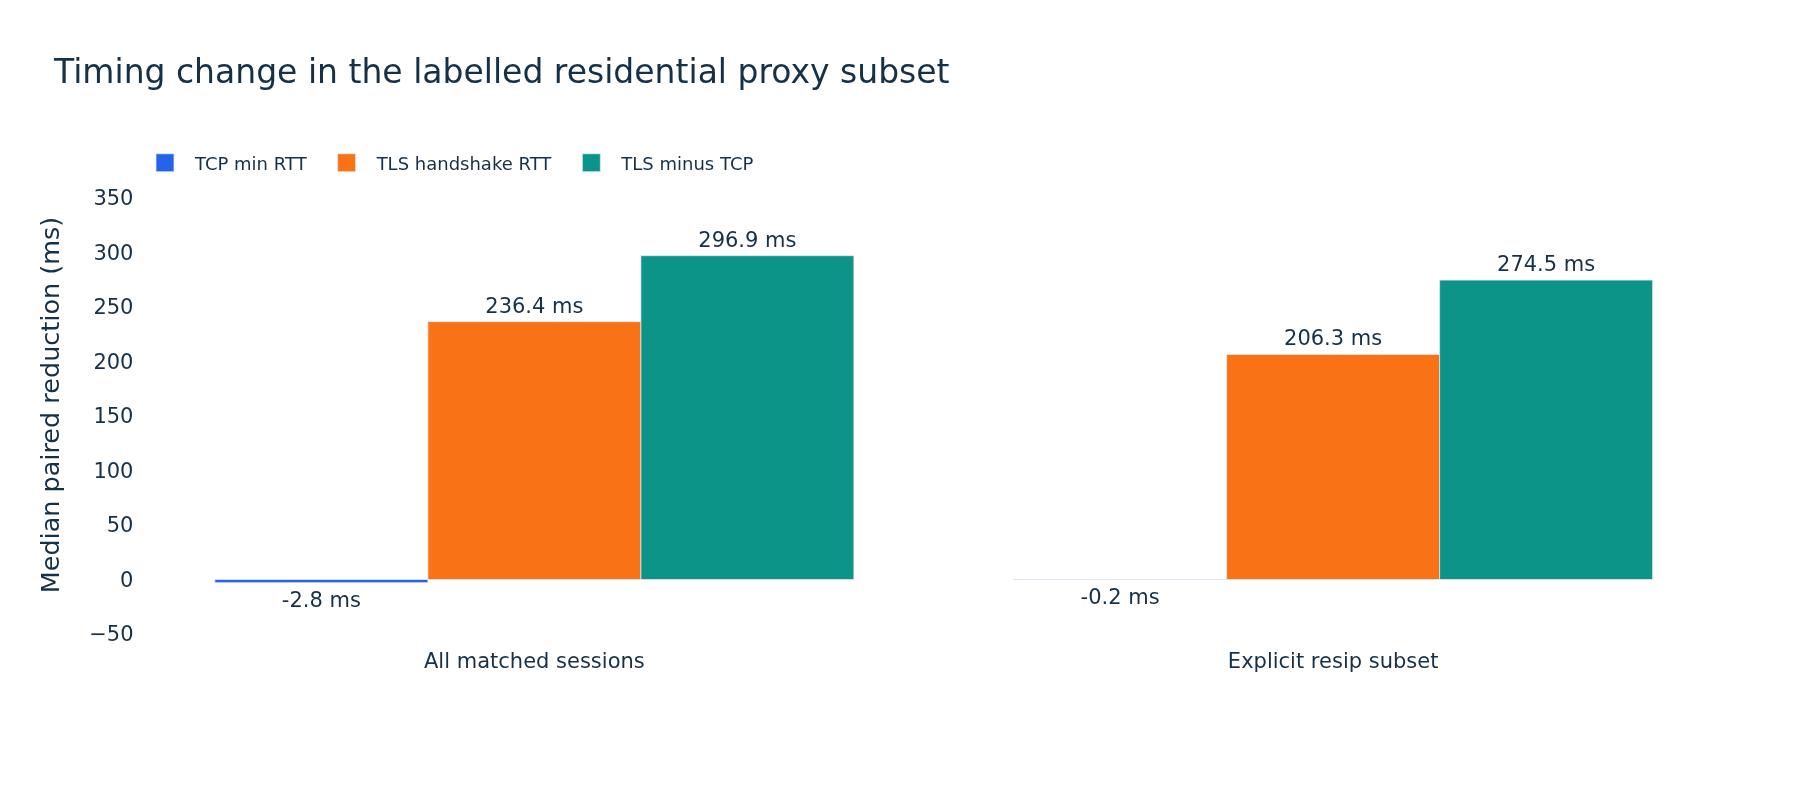
The TLS reduction was about 206 ms in the labelled subset. These timing values support a connection-path difference and cannot locate JavaScript execution.
Timing comparison groups overlap
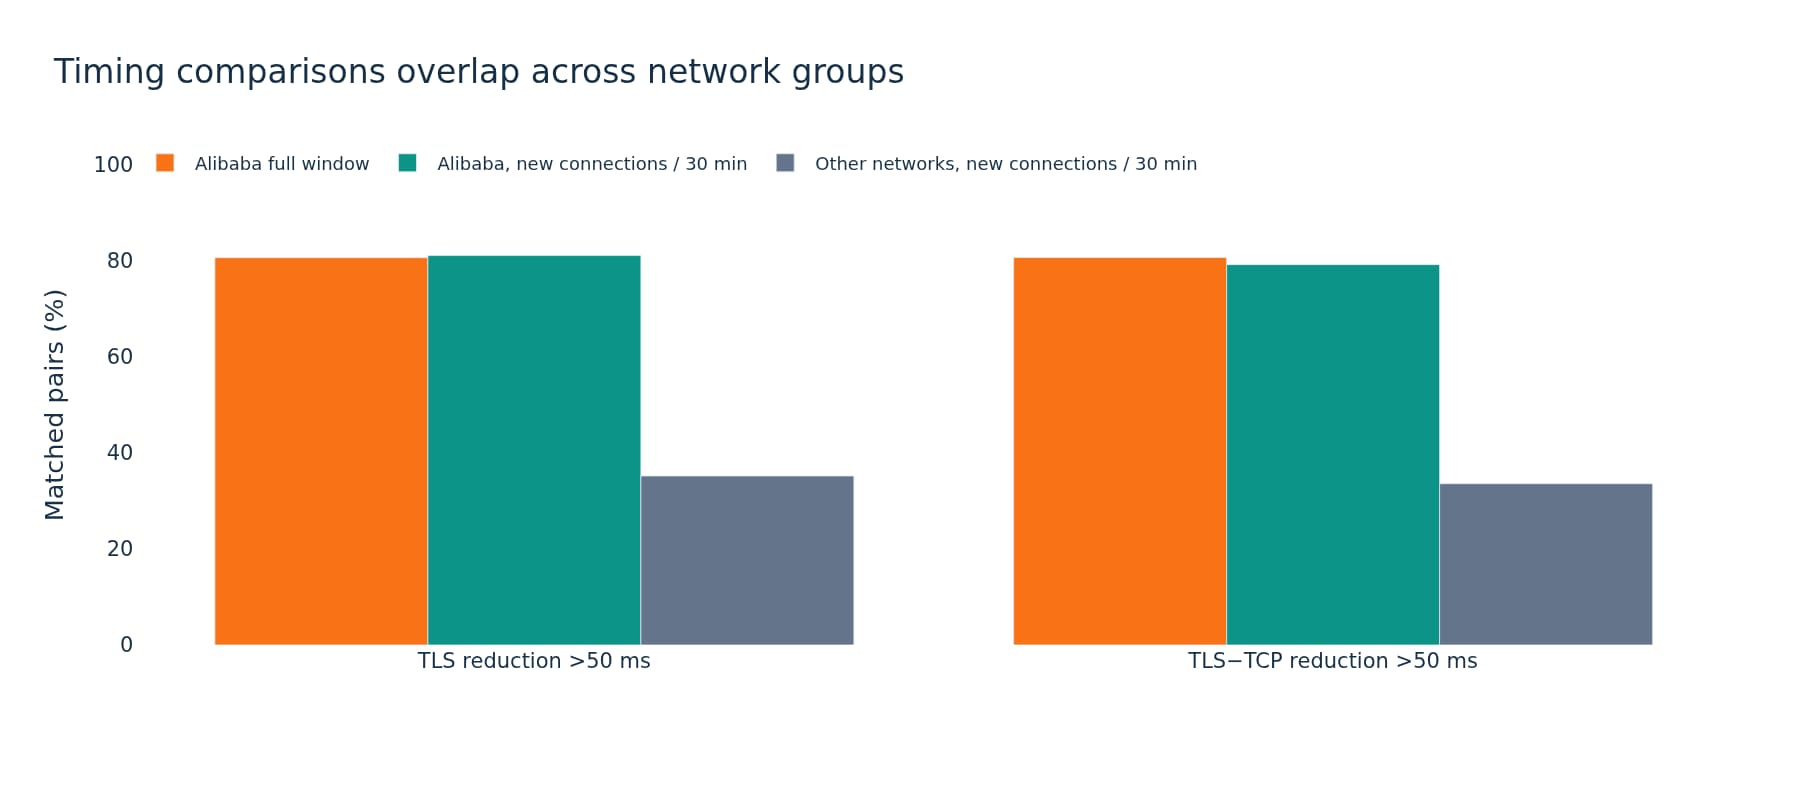
The full-window Alibaba group and two 30-minute comparison groups have different coverage. Their overlap shows why a timing threshold alone is insufficient.
Address use within the four ranges
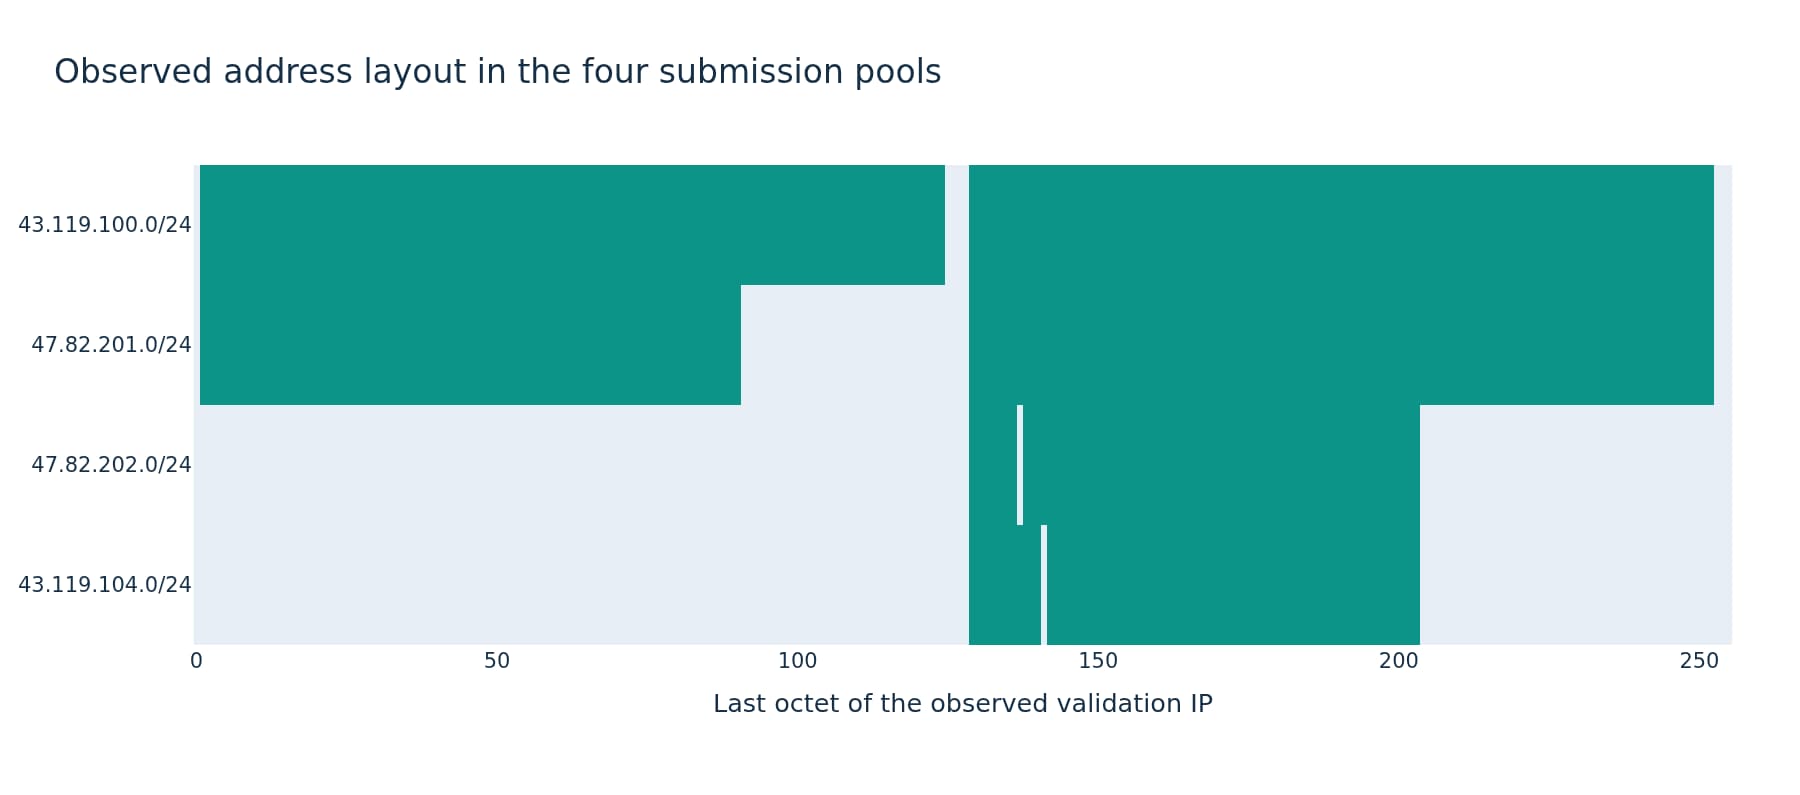
The chart preserves the observed address layout. It does not count virtual machines, containers or operators.
A wider search found the same submission pools
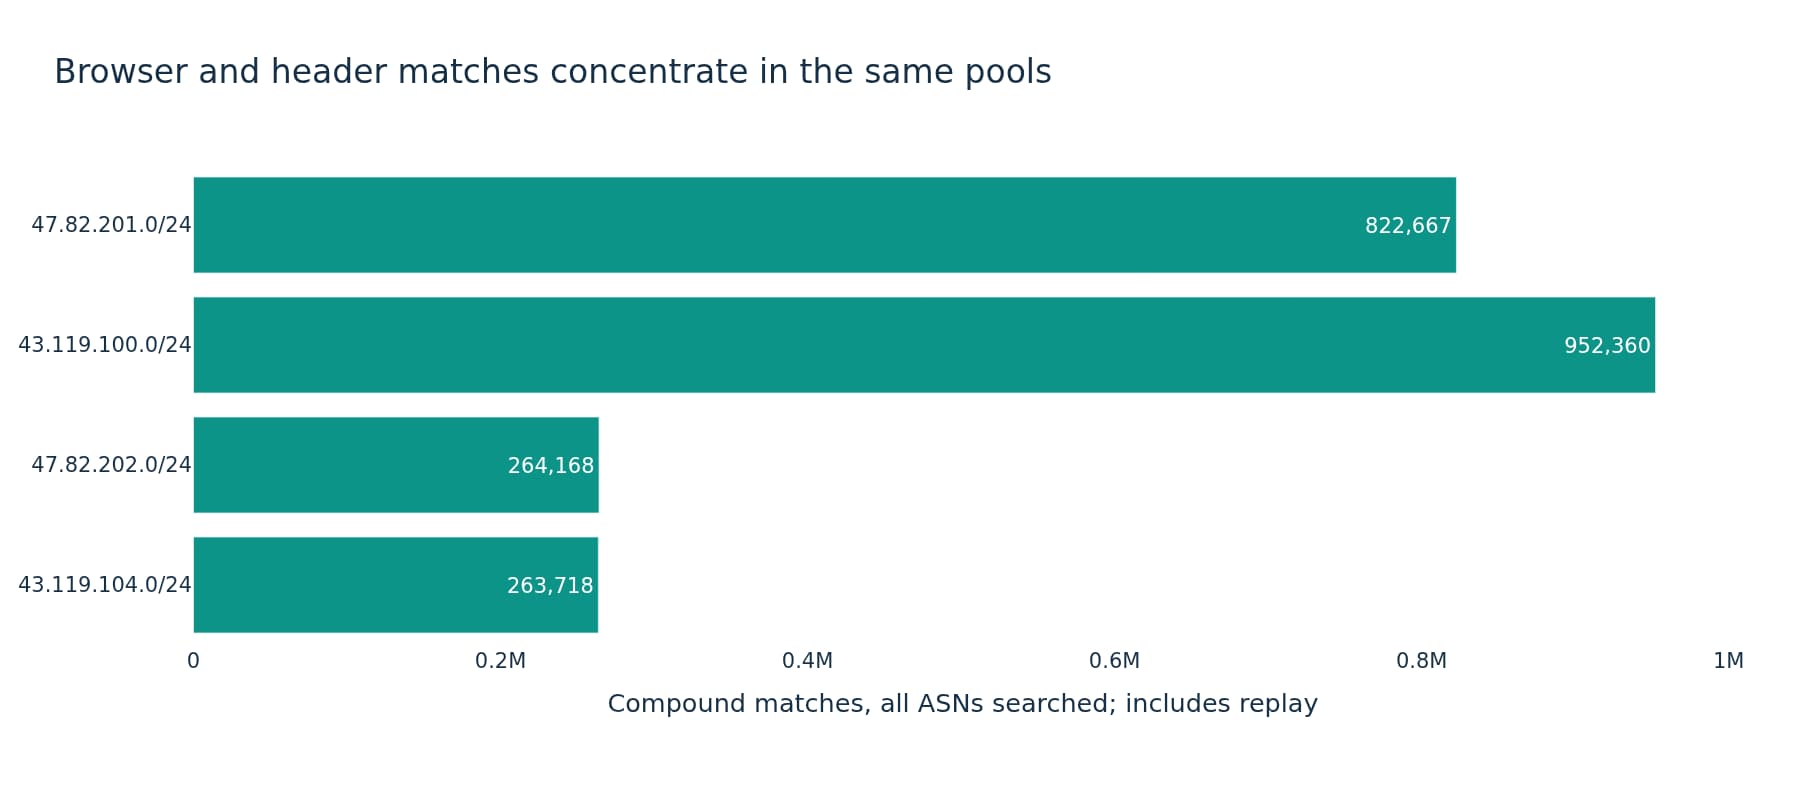
A search using browser and header traits, without requiring a provider, country or one TLS fingerprint, found 2,302,914 matched submission records. The four bars show the 2,302,913 in-pool matches. The single outside-pool match was rejected and is excluded from those bars. This search still follows a known profile.
Reported CPU counts followed a regular pattern
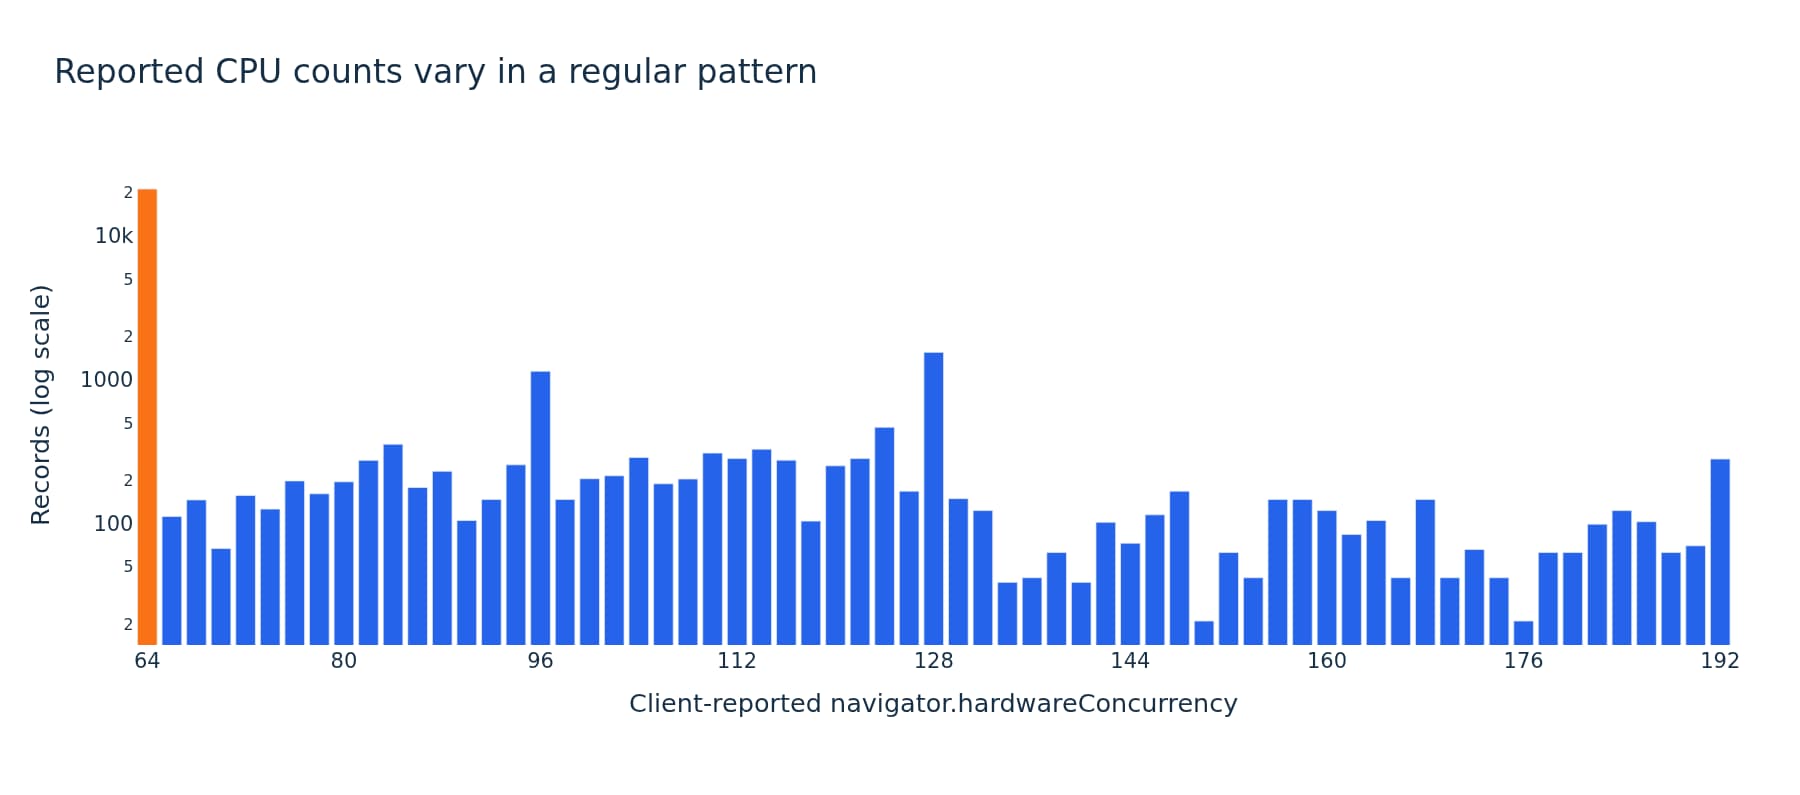
The browser payload reported every even value from 64 to 192. These are reported properties, rather than measurements of physical hardware.
What the four pools sent
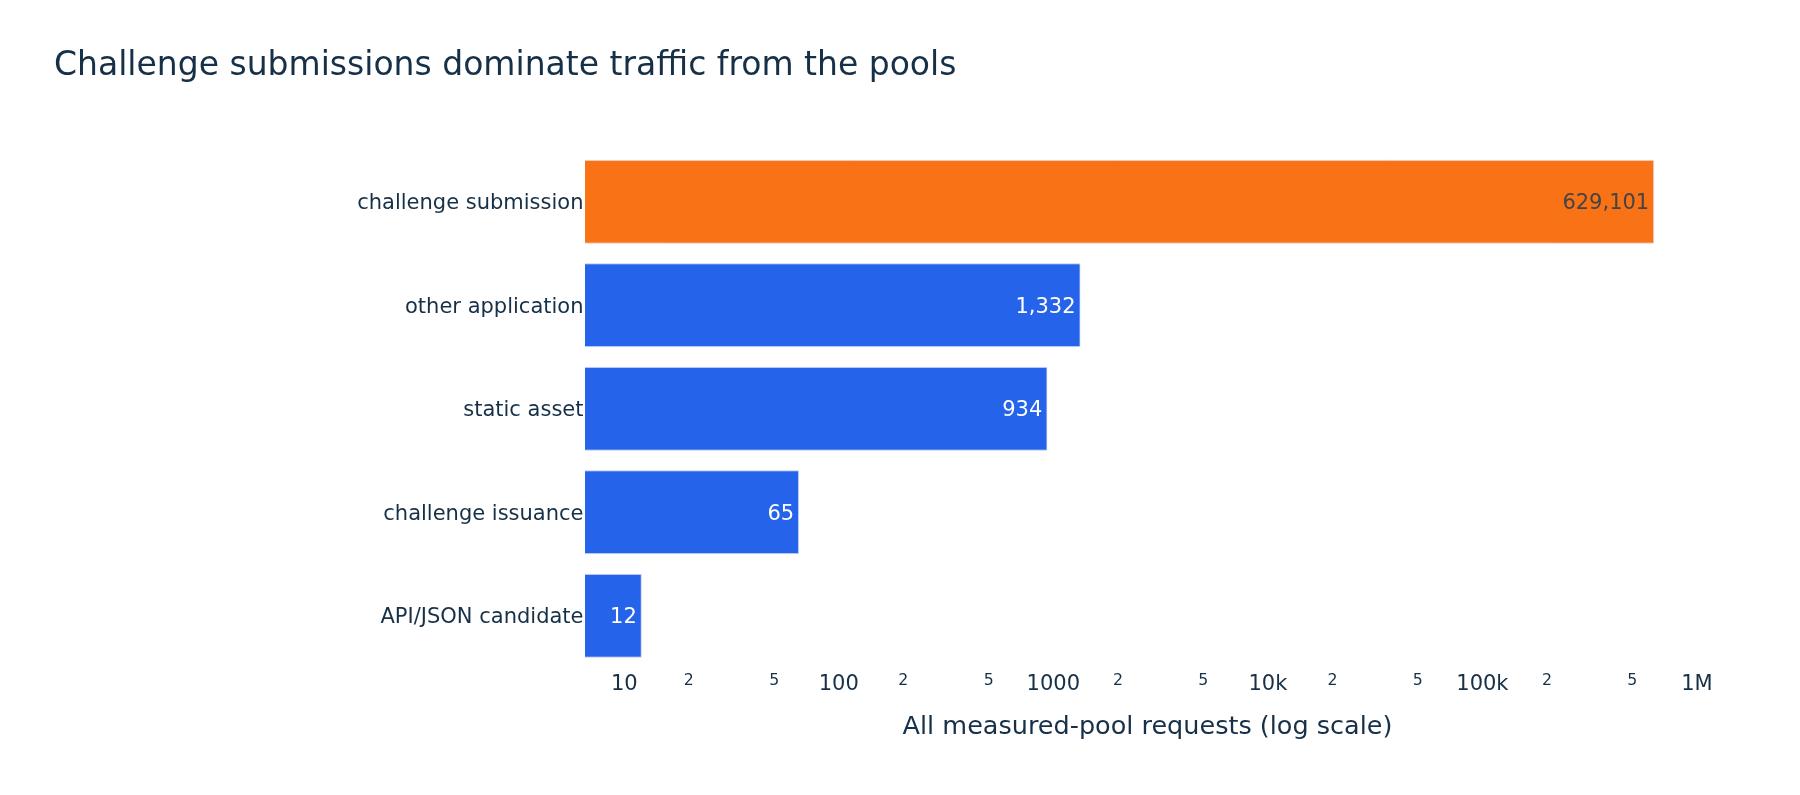
In the narrower follow-up, 99.63% of pool requests were challenge submissions. The API/JSON category is inferred from paths and headers; it does not establish data retrieval.
The Lightpanda lead remained weak
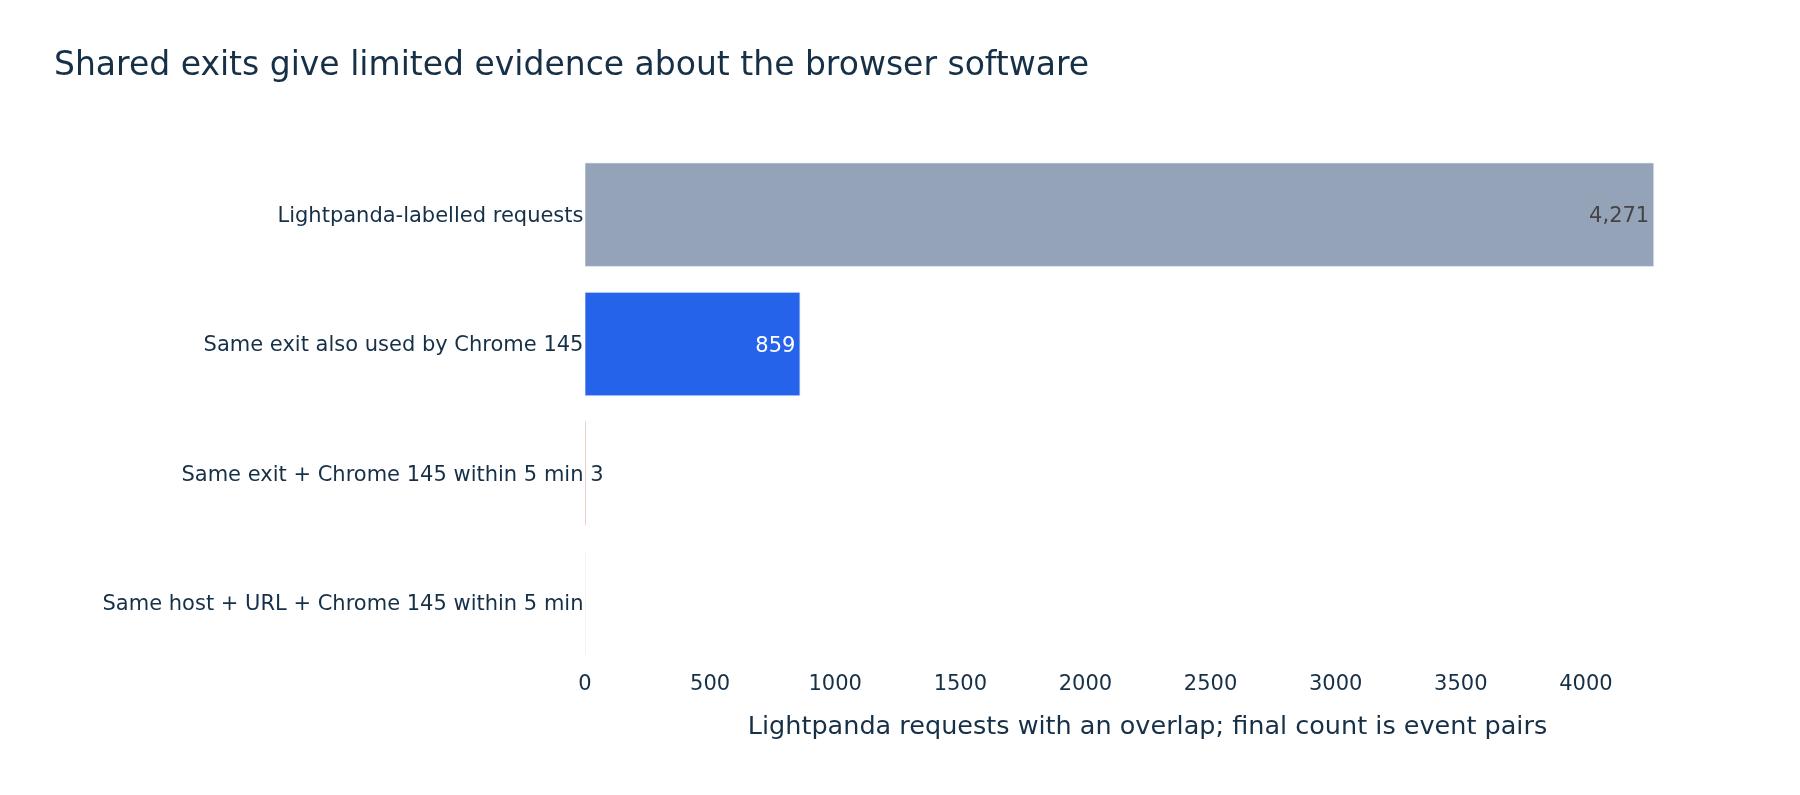
A separate 20 October to 27 October sample contained 4,271 labelled requests. Close shared-exit matches did not establish a matching site-and-URL request sequence. Shared exits can carry unrelated traffic.
All four pools stayed active
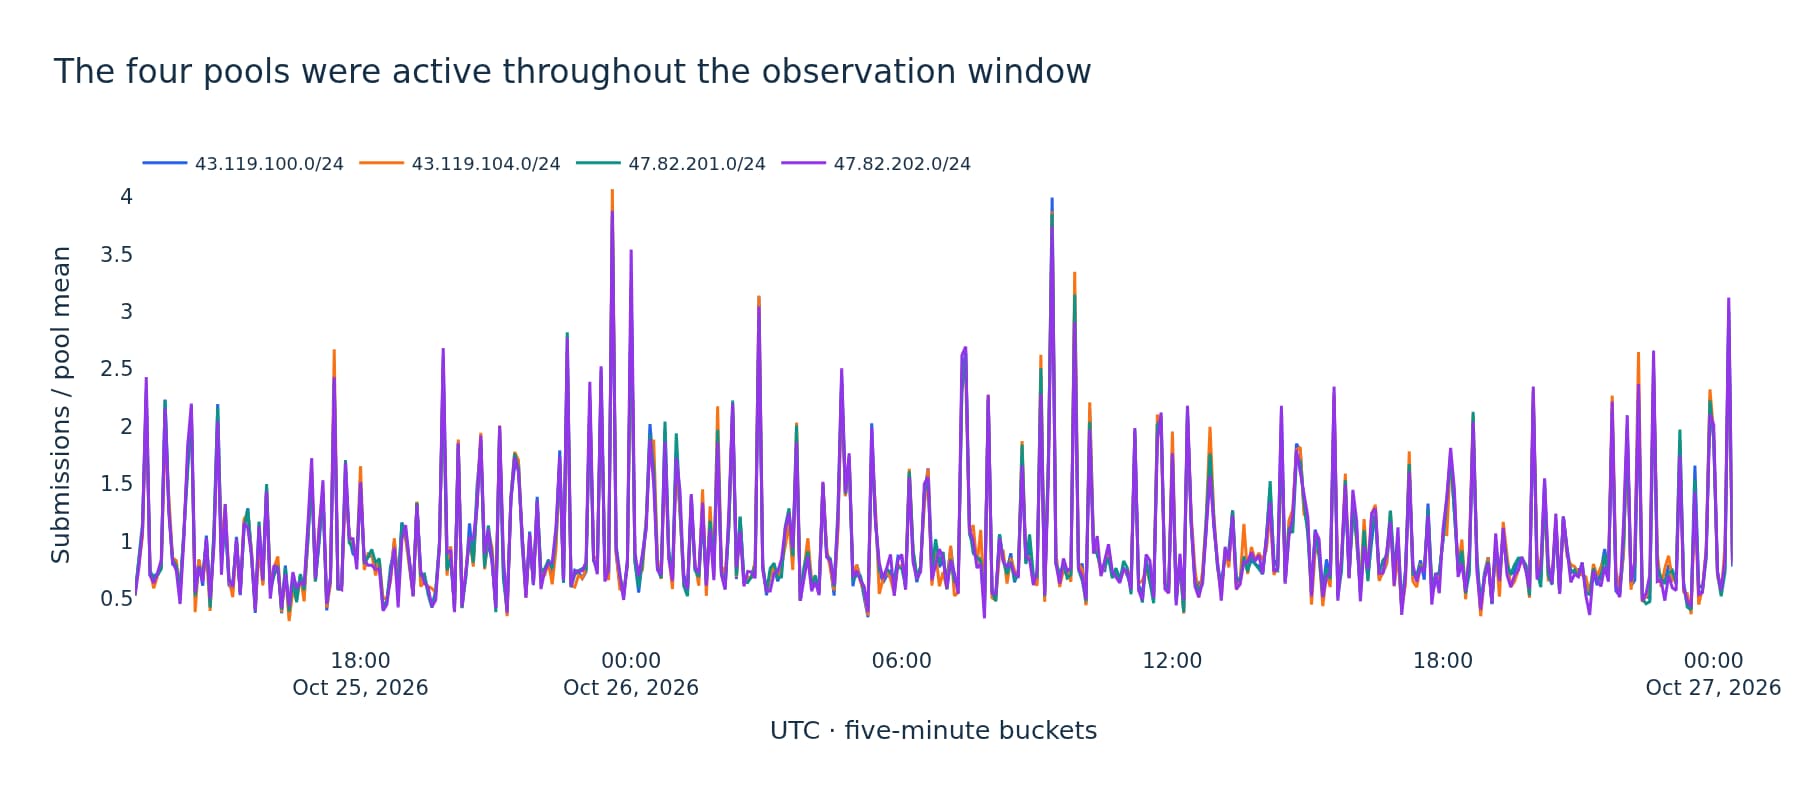
Five-minute activity in the narrower follow-up window, labelled in UTC. Shared repeated answers explain some of the timing agreement.
The selected browser profile recurred over time
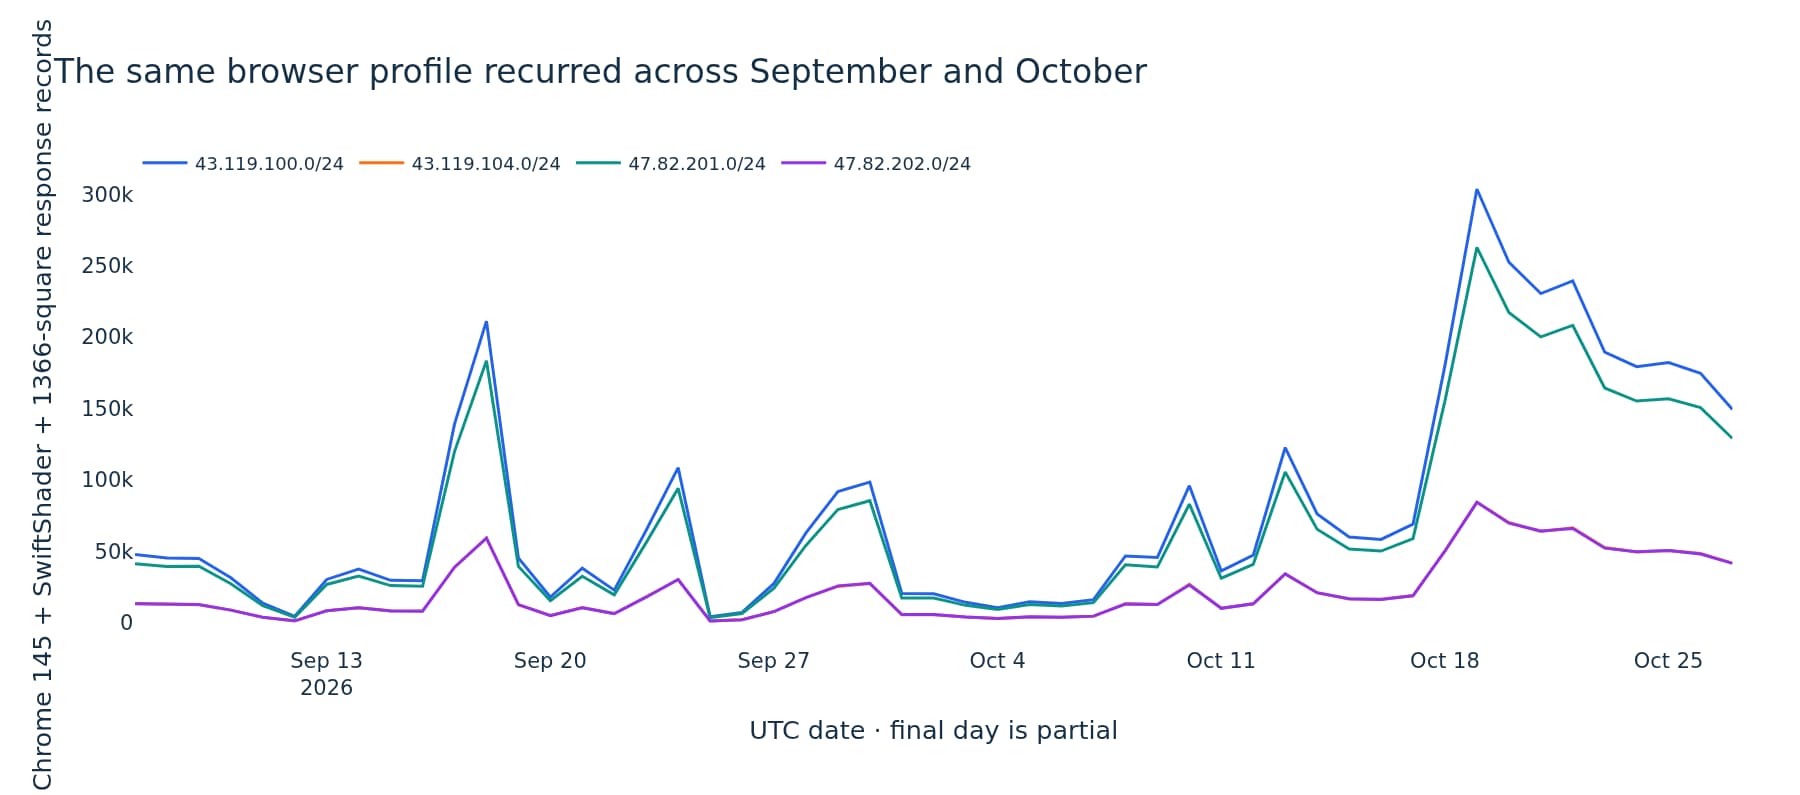
This series requires the selected User-Agent, SwiftShader and square viewport. Counts are challenge-response records, including repeats, in UTC daily buckets.
Matching traffic continued in our observations
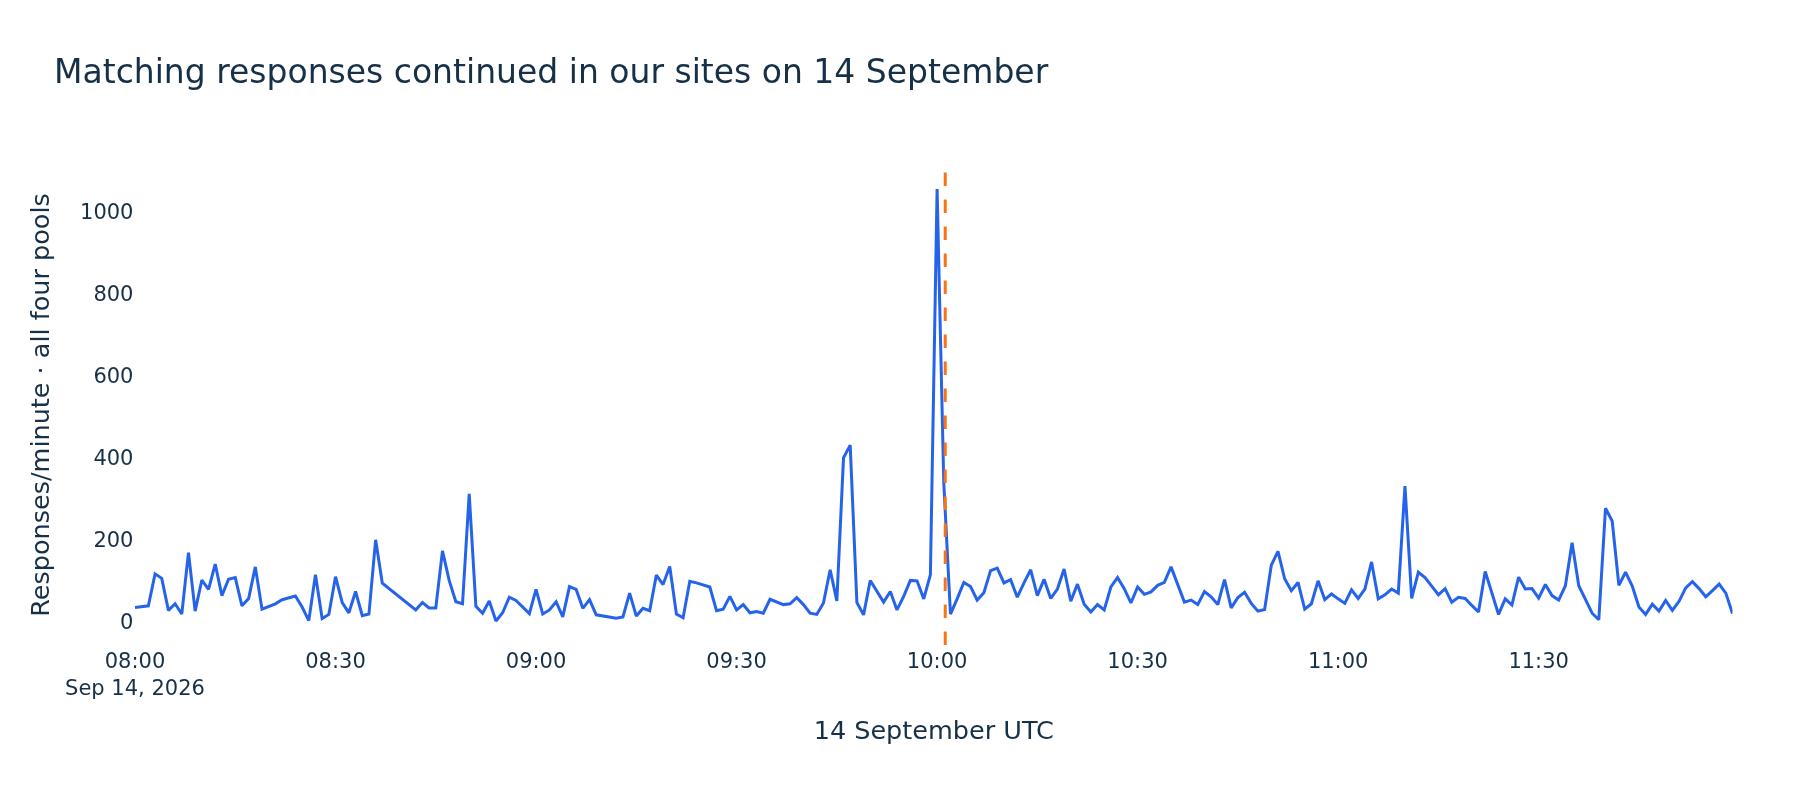
The vertical reference comes from the separate public report. Continued activity at our sites cannot establish that its reported shutdown was wrong or that both observations have one operator. Times are UTC.
The browser claim appeared before the traced replay
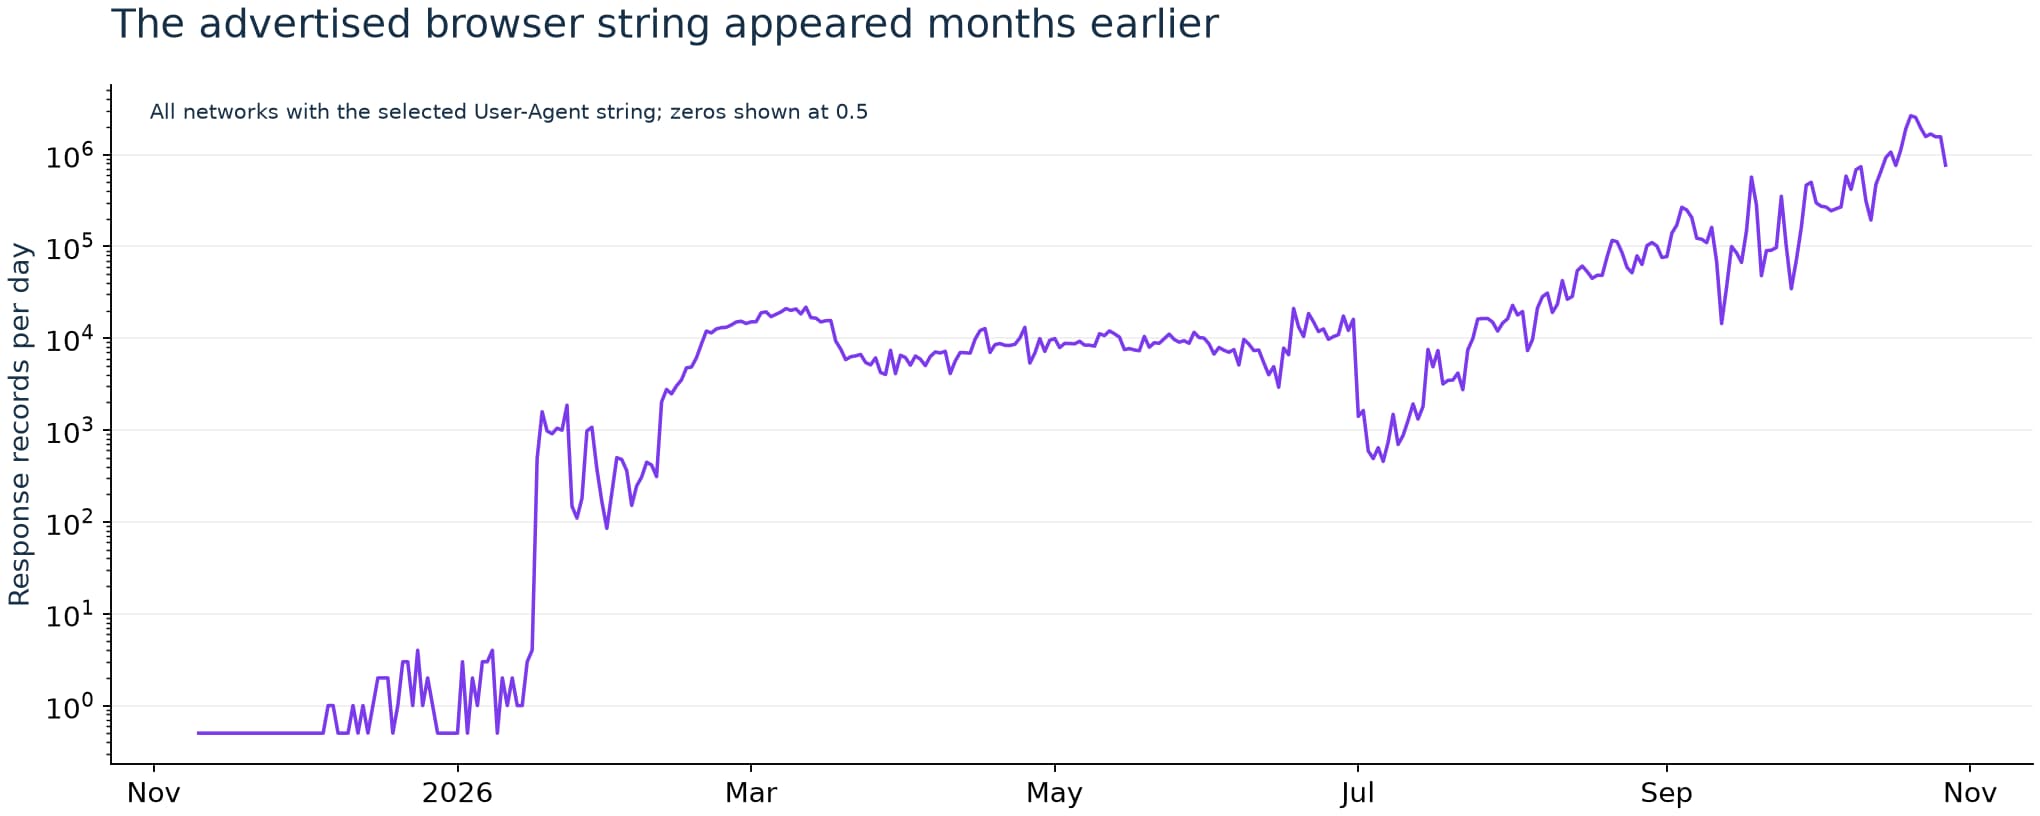
This is the selected User-Agent string across all networks. The log scale plots zero counts at 0.5. The string alone cannot establish that earlier requests belonged to this workload.
Missing network names changed the view
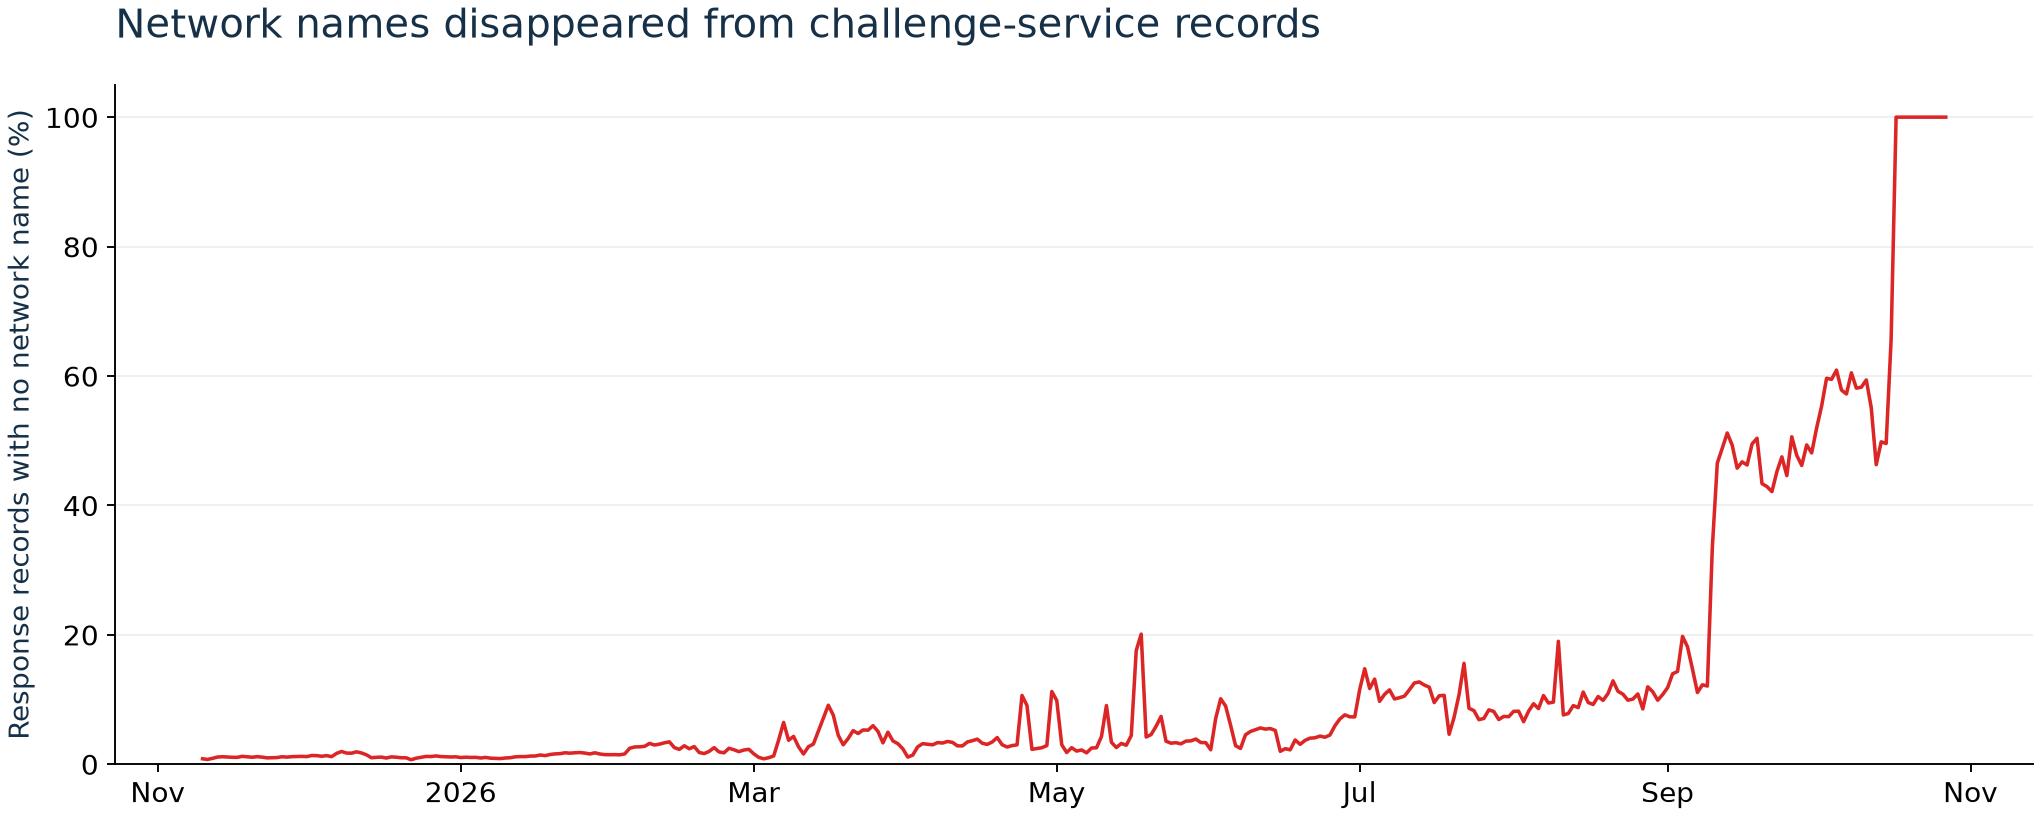
Network names were blank in all challenge-service responses from 17 October onward. Edge request records still showed Alibaba traffic. A missing label must remain unknown.
How we checked the results
The main analysis paired the original request and first submission by site and session, then linked each challenge decision to its exact request identifier. We checked chronology and address agreement. This avoids multiplying retries through a broad session-only join.
The historical charts combine daily edge counts with separately labelled challenge-service series. Some service records lost their network name even while the edge records continued to show the traffic. Missing attribution was kept unknown.
Timing comparisons exclude every hostname containing edge and use requests handled at the same point of presence, meaning the same service location. Timing supports the connection-path comparison; it cannot locate the software executing the challenge.
We collected the records for these reports using read-only queries. This article describes the saved investigation and does not claim a new November scan or a deployed fix. Customer names, raw session identifiers and challenge answers are omitted.